MAG-u resiliency
The Nokia MAG-c supports a MAG-c-driven MAG-u resiliency scheme. Learn about this resiliency scheme, the resiliency handling, and deployment use cases.
Terminology for MAG-u resiliency
- fate sharing group (FSG)
- An FSG is a group of sessions that stay together when moved between MAG-u nodes. This guarantees that any associated resources, such as ODSA allocated prefixes, are moved together with the sessions. This maps to the TR-459 concept of a subscriber group (SGRP); FSGs use the PFCP extensions for SGRPs defined in TR-459. In the context of PFCP, the terms FSG and SGRP are interchangeable.
- active MAG-u
- In the scope of a single FSG, the active MAG-u is the MAG-u on which the sessions are created and that actively forwards traffic for those sessions.
- standby MAG-u
- In the scope of a single FSG, the standby MAG-u indicates the MAG-u that is ready to install sessions and forward traffic upon failure of the active MAG-u. Whether sessions are proactively created on this MAG-u depends on the chosen resiliency model.
- hot standby
- In the hot standby resiliency model, sessions are proactively created on a standby MAG-u. The standby MAG-u does not attract traffic but is ready to start forwarding as soon as the MAG-c instructs it to do so.
Introduction to MAG-c-driven MAG-u resiliency
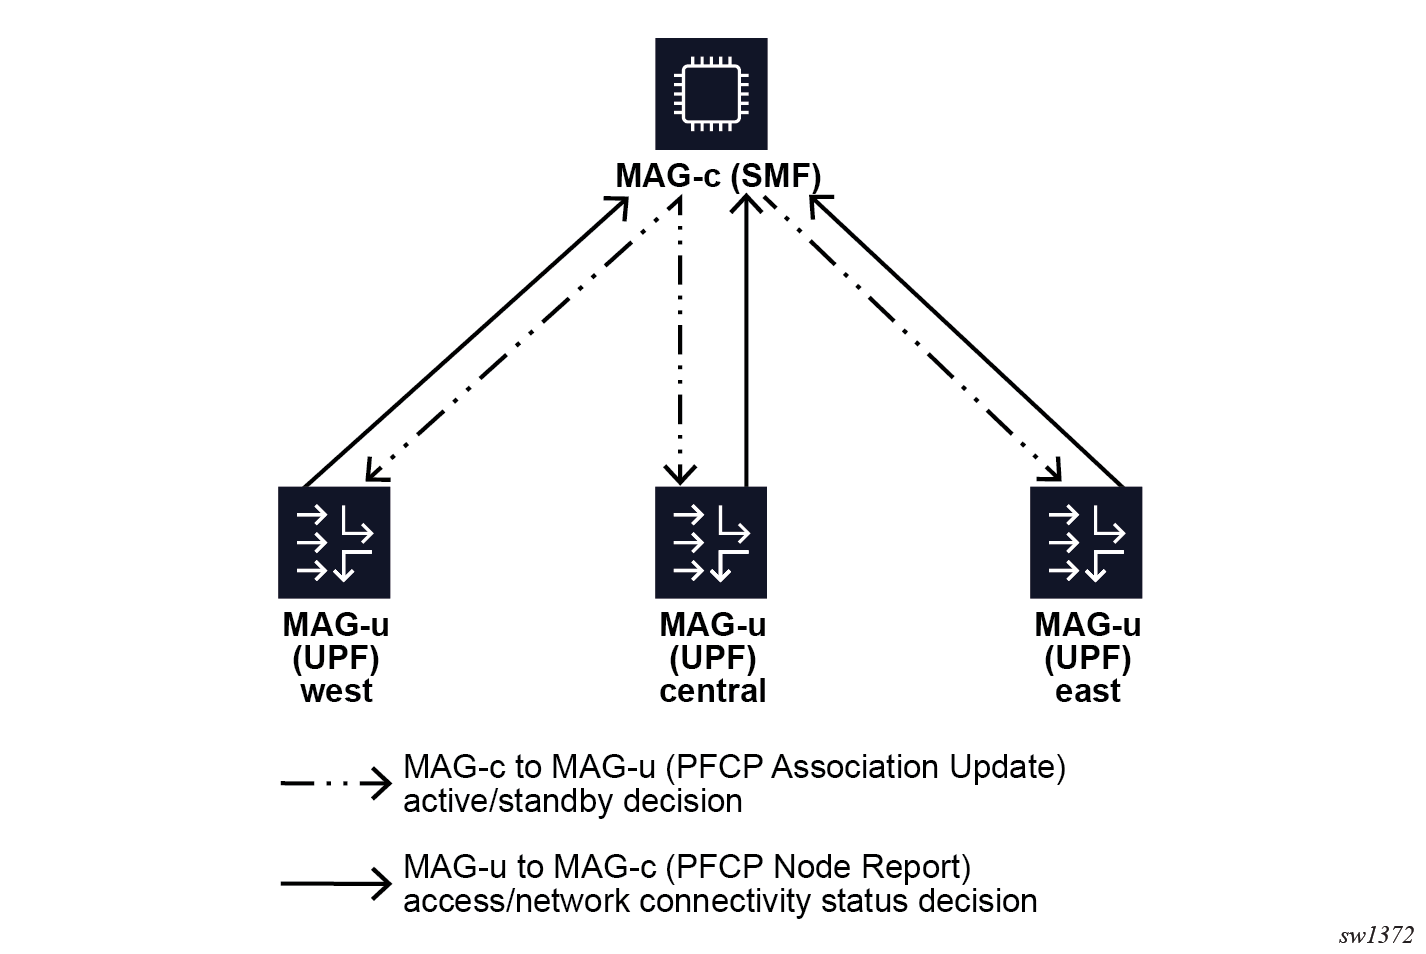
The Nokia MAG-c supports a MAG-c-driven MAG-u resiliency scheme. In this scheme, the MAG-c selects the active and standby MAG-u nodes and the MAG-u nodes must follow this decision. The MAG-u nodes do not communicate directly to negotiate the active or standby role or to synchronize session state. Instead, each MAG-u sends its local status indicators to the MAG-c ; for example, whether it has full connectivity to the access network. The MAG-c aggregates these status indicators from all MAG-u nodes and makes an informed decision that is sent to the MAG-u nodes. The PFCP node messages of the PFCP association between the MAG-u and MAG-c that are already in place for session management carry the status indicators and informed decisions.
The following figure shows a high-level overview of communication for MAG-u resiliency.
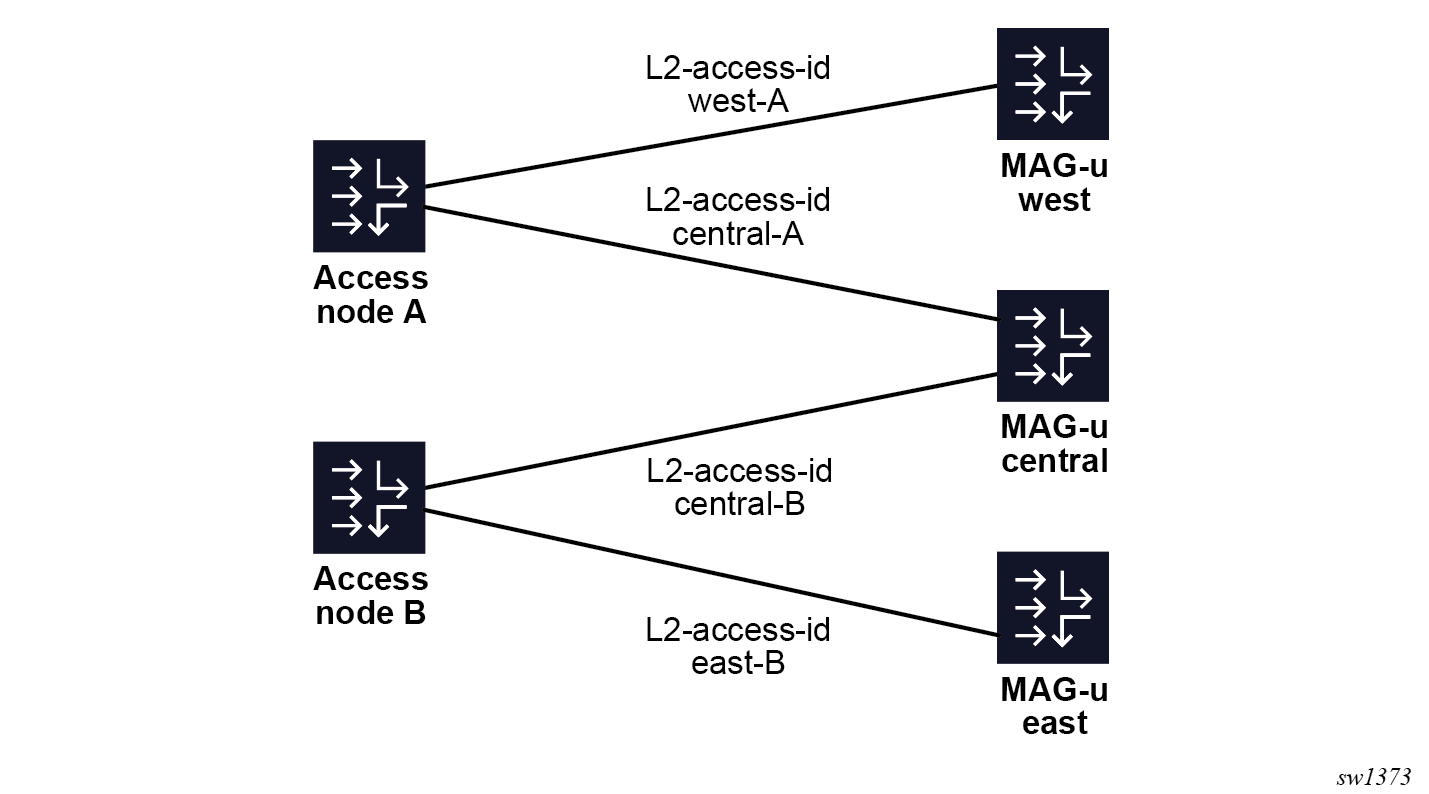
It is possible and often wanted that a MAG-u is active for a subset of the sessions and standby for another subset of the sessions. For example, when two MAG-u nodes are fully available, making both MAG-u nodes active for half of the sessions and standby for the other half of the sessions may be preferred. Similarly, two Layer 2 access IDs (ports) on the same MAG-u can be backed up by two different MAG-u nodes. The following figure shows the use case where the MAG-u "central" is backed up by both the MAG-u nodes "west" and "east" for two different Layer 2 access IDs.
To support all use cases, the MAG-c assigns sessions to an FSG. The MAG-c assigns the active or standby state to each FSG. The state applies to all sessions of the FSG, but not to any other session on the same MAG-u nodes. ODSA is also FSG-aware and allocates micro-nets on an FSG basis, instead of a MAG-u basis, to account for FSGs moving between MAG-u nodes.
Modeling a resilient MAG-u deployment using UP groups
The UP group configuration is a key component of the CUPS MAG-u resiliency. This configuration serves as a high-level description of the MAG-u access network so that the MAG-c knows which MAG-u nodes are interconnected for MAG-u resiliency. Based on the UP group configuration, the MAG-c automatically generates FSGs for the resiliency functionality. The UP group contains parameters to create the FSGs.
configure mobile-gateway pdn bng up-groupAt the core of the UP group configuration is a list of MAG-u nodes. The PFCP node ID IE as signaled during the PFCP association setup procedure identifies each MAG-u. The identifier can be either a name or an IP address. The MAG-u nodes that form the UP group are interconnected and MAG-u resiliency can occur between them.
configure mobile-gateway pdn bng up-group force-fqdn-node-idFate sharing group creation
The MAG-c automatically creates FSGs for every configured UP group. The following configuration for the FSG is provisioned via the UP group:
- reference to an FSG profileUse the following command to configure the FSG mode.
configure mobile-gateway pdn bng up-group fsg-modeCurrently, the following FSG modes are available:- single – a single FSG is generated for the whole UP group and all sessions matching the group are assigned to that FSG
- mesh-per-site – a mesh of FSGs is generated for each site configured in the UP group and sessions are automatically assigned to an FSG (see FWA MAG-u mesh for more information about this model)
- reference to an FSG profileUse the following command to configure a reference to an FSG profile.
The profile contains detailed parameters on the resiliency behavior; for example, health calculation for each MAG-u.configure mobile-gateway profile bng fsg-profile - preferred indicatorPer MAG-u, a flag indicates whether the MAG-u is active by preference. When the flag is set for a MAG-u, the FSG prefers this MAG-u to be active if all other parameters are equal.Note: The preferred indicator is not configurable when fsg-mode is set to mesh-per-site.
- drain indicator
Per MAG-u, a flag indicates whether the MAG-u is in drain mode. When the flag is set for a MAG-u, the FSG avoids selecting this MAG-u as active. For example, this flag can be used before upgrading a MAG-u to achieve a graceful switchover.
Note: Changing the drain flag for an active MAG-u acts as a MAG-u reselection trigger for the linked FSGs. The MAG-c moves the sessions after changing the configuration.
Fixed access with broadcast access
Fixed access sessions require the Layer 2 circuit (Layer 2 access ID and VLAN parameters) that is learned from incoming IBCP packets. In a resilient setting, the Layer 2 circuits can differ between the MAG-u nodes. For example, in Multiple backup MAG-u nodes, Layer 2 access ID "central-A" on MAG-u "central" is backed up by Layer 2 access ID "west-A" on MAG-u "west". Because the MAG-c cannot rely on the initial IBCP messages to learn all the Layer 2 access IDs, the IDs must be configured manually.
A single Layer 2 access ID can be configured per MAG-u in a UP group. When setting up a new session for this UP group, the MAG-c learns the initial Layer 2 access ID from the incoming IBCP packet, but derives the Layer 2 access IDs for the other MAG-u nodes from the configuration. A MAG-u group-level default can be configured to simplify cases where the Layer 2 access IDs are identically named. See Example for a 1:1 hot standby resiliency with an S-tag per access node for this use case.
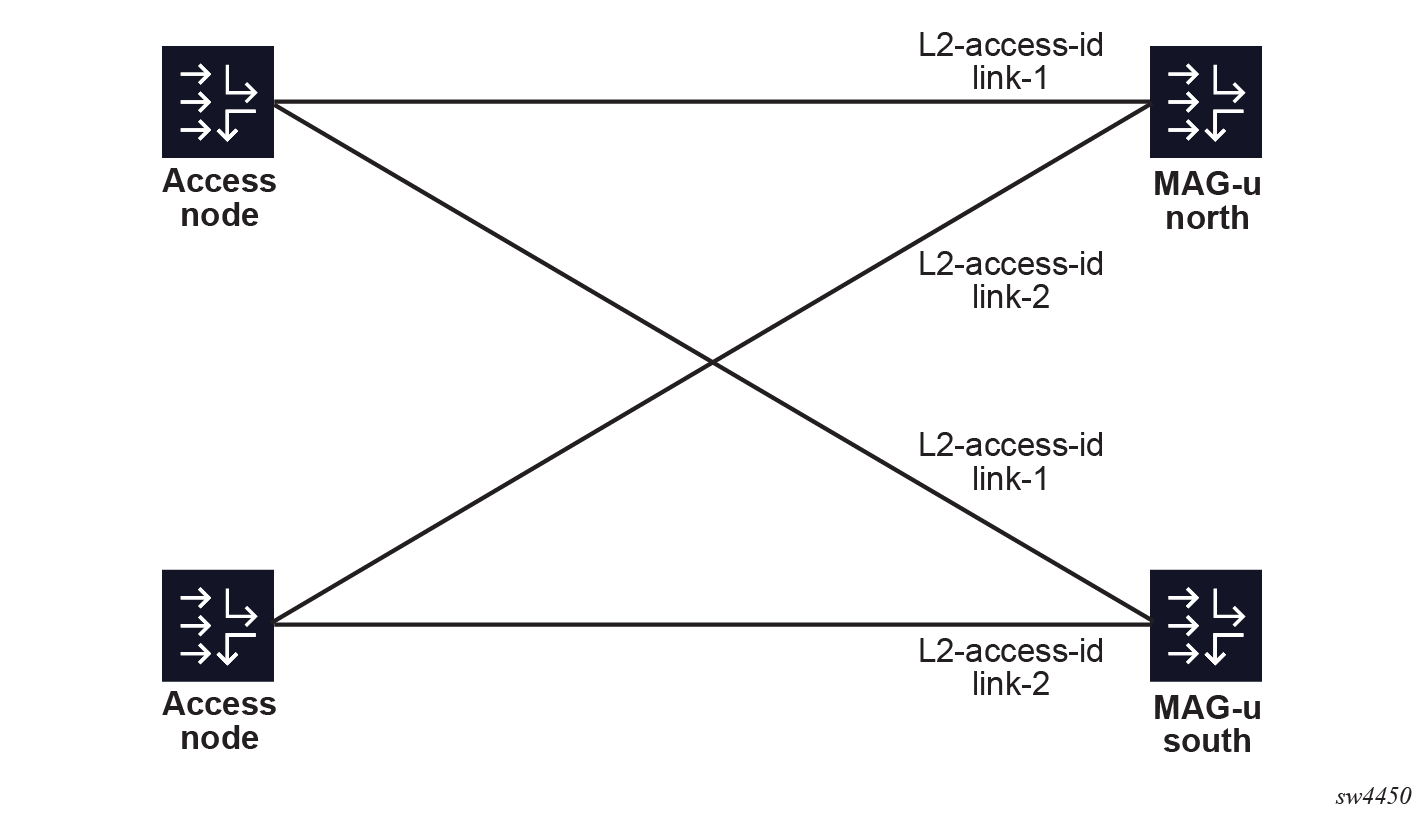
When all MAG-u nodes use identical Layer 2 access IDs, it is possible to list multiple Layer 2 access IDs per UP group at the group level to avoid creating multiple UP groups for each Layer 2 access ID. When this is configured, the MAG-u assumes that each Layer 2 access ID is backed up by the identically named Layer 2 access ID on other MAG-u nodes. The MAG-c does not assume that there is one big broadcast domain shared between all ports. The following figure shows a UP group that covers two Layer 2 access IDs, named "link-1" and "link2". The sessions on "link-1" cannot be backed up on "link-2" because "link-2" connects to another access node.
up-group "demo"
    fsg-profile "empty"
    l2-access-id link-1 link-2
    up "north"
    exit
    up "south"
    exit
    no shutdown
exit
Similarly, a VLAN range can be configured per MAG-u for both S-tags and C-tags. A UP group-level default is also available. The VLAN range configuration serves the following purposes:
- Split a single Layer 2 access ID in multiple FSGs and set a different preferred status on different MAG-u nodes. In stable conditions, this achieves active/active behavior where some sessions are active on one MAG-u while others are active on another MAG-u. See Example for a 1:1 hot standby resiliency with an S-tag per access node for this use case.
- Set different VLAN ranges on several MAG-us in
more complex aggregation requirements. The MAG-c automatically adjusts the VLANs learned from IBCP for each MAG-u
based on the difference between the start values of the VLAN ranges of each MAG-u. For
example, if MAG-u A is
configured with range 100 to 200, and MAG-u B
with range 500 to 600, a session with VLAN 150 on MAG-u A
automatically uses VLAN 550 on MAG-u B.
While the start values of the VLAN range can be different, all ranges must have an
equal size. For example, it is not possible to configure a range of 100 to 200 on
one MAG-u,
and 100 to 300 on another MAG-u in
the same UP group.WARNING: VLAN ranges with a different offset over more MAG-u nodes are an advanced use case and should be carefully validated against the deployed aggregation network. To avoid accidentally enabling different offsets when this functionality is not required, Nokia recommends only configuring a VLAN range on the UP group level.
The following subsections provide deployment use cases and example UP group configurations for the MAG-u resiliency concepts.
Example for a 1:1 hot standby resiliency with an S-tag per access node
Four access nodes are connected to a pair of MAG-us using a shared broadcast domain. To simplify Layer 2 forwarding, each access node is assigned a unique S-tag. The broadcast domain is connected to each MAG-u through an identically-named Layer 2 access ID on both MAG-u nodes. The MAG-c makes abstraction of whether this connection is a port, LAG, BGP-VPLS, EVPN, or any similar construct.
- MD-CLI
configure service vpls capture-sap pfcp l2-access-id-alias - classic
CLI
configure service vpls sap pfcp l2-access-id-alias
- Split the Layer 2 access IDs based on S-tag ranges in two UP groups, each serving half of the access nodes.
- Configure a different MAG-u as preferred in each group to make the associated FSG active on the preferred MAG-u as long as that MAG-u is healthy.
- Link to an empty FSG profile to make the default session standby mode equal to hot (see Hot standby for more information).
up-group "prefer-east"
    fsg-profile "empty"
    s-tag-range start 1 end 2
    l2-access-id to-access
    up "east"
        preferred
    exit
    up "west"
    exit
    no shutdown
up-group "prefer-west"
    fsg-profile "empty"
    s-tag-range start 3 end 4
    l2-access-id to-access
    up "east"
    exit
    up "west"
        preferred
    exit
    no shutdown
The following figure shows an example for a 1:1 hot standby resiliency with an S-tag per access node.
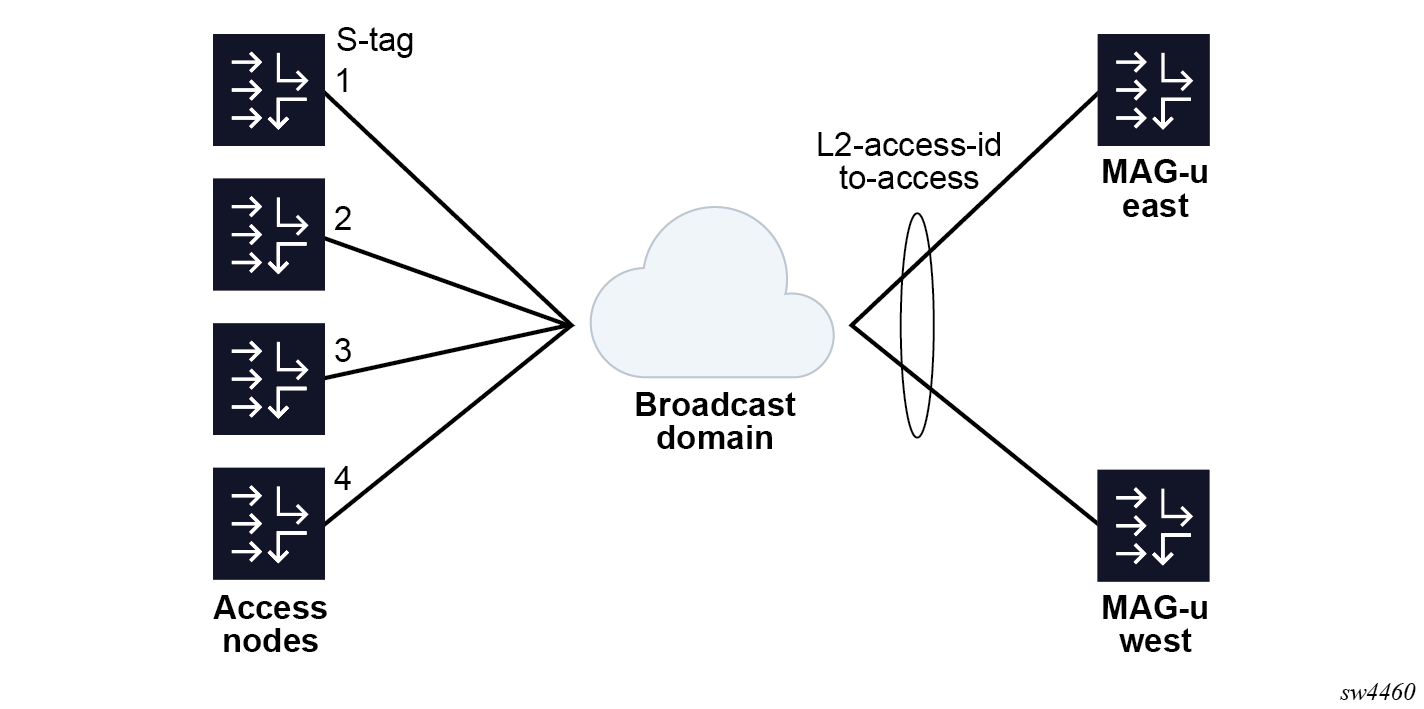
Example for a per S-tag 1:1 hot standby resiliency with an S-tag per access node
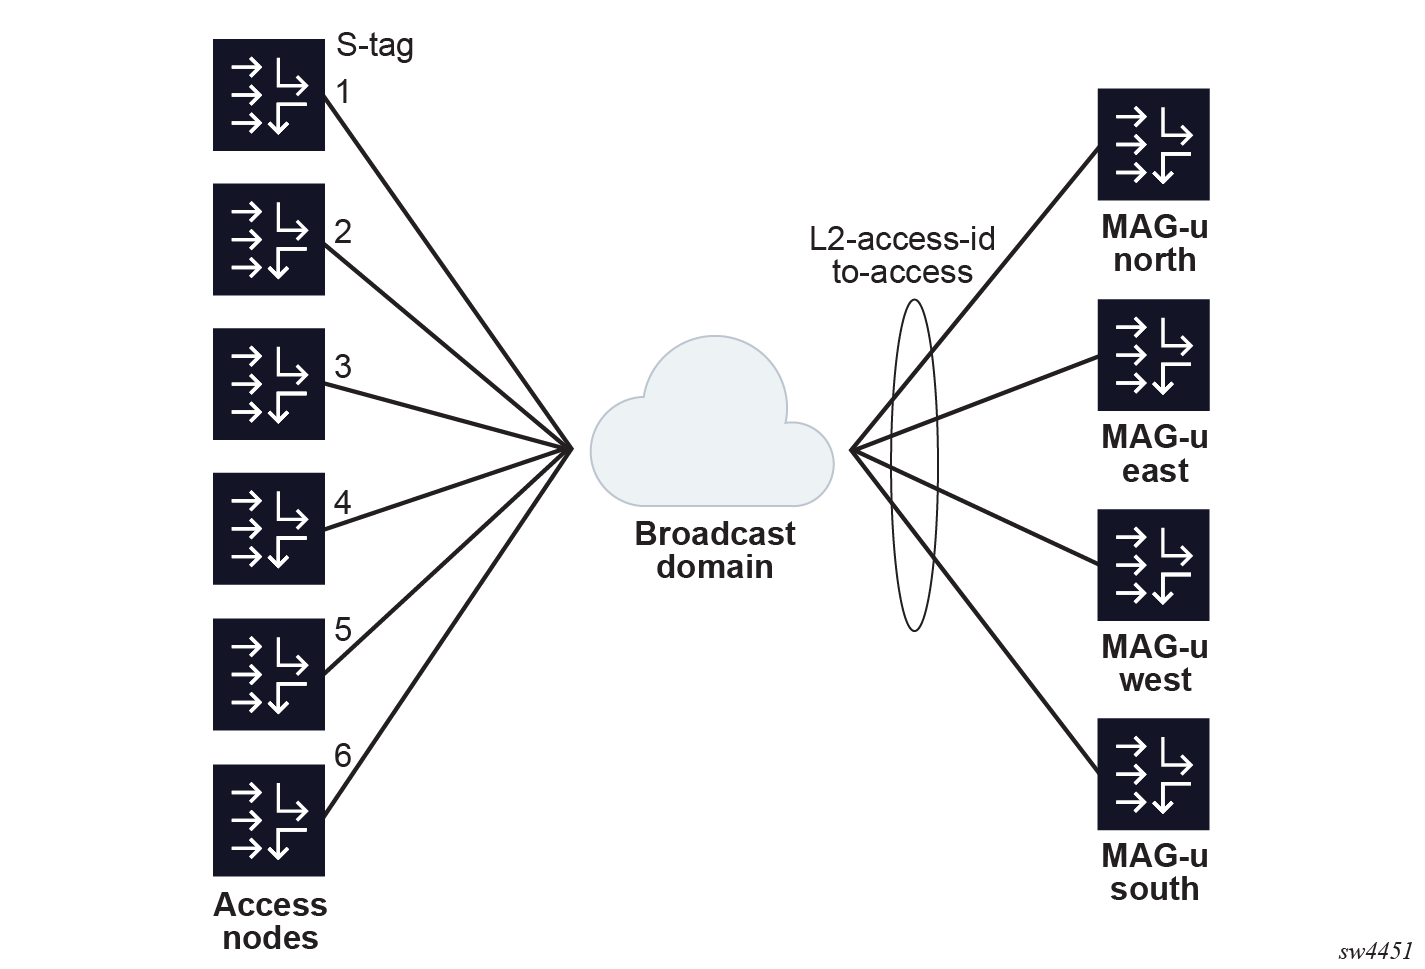
This example extends the previous model with two access nodes and two MAG-u nodes.
Instead of splitting the MAG-u nodes such that there are two pairs of 1:1 MAG-u nodes, each S-tag range gets a different pair of standby MAG-u nodes as follows:
- S-tag 1 is backed by MAG-u "north" and "east"
- S-tag 2 is backed by MAG-u "east" and "west"
- S-tag 3 is backed by MAG-u "west" and "south"
- S-tag 4 is backed by MAG-u "south" and "north"
- S-tag 5 is backed by MAG-u "north" and "west"
- S-tag 6 is backed by MAG-u "east" and "south"
up-group "s-tag-1"
    fsg-profile "empty"
    s-tag-range start 1 end 1
    l2-access-id to-access
    up "north"
    exit
    up "east"
    exit
    no shutdown
up-group "s-tag-2"
    fsg-profile "empty"
    s-tag-range start 2 end 2
    l2-access-id to-access
    up "east"
    exit
    up "west"
    exit
    no shutdown
up-group "s-tag-3"
    fsg-profile "empty"
    s-tag-range start 3 end 3
    l2-access-id to-access
    up "west"
    exit
    up "south"
    exit
    no shutdown
up-group "s-tag-4"
    fsg-profile "empty"
    s-tag-range start 4 end 4
    l2-access-id to-access
    up "south"
    exit
    up "north"
    exit
    no shutdown
up-group "s-tag-5"
    fsg-profile "empty"
    s-tag-range start 5 end 5
    l2-access-id to-access
    up "north"
    exit
    up "west"
    exit
    no shutdown
up-group "s-tag-6"
    fsg-profile "empty"
    s-tag-range start 6 end 6
    l2-access-id to-access
    up "east"
    exit
    up "south"
    exit
    no shutdown
The following figure shows an example of a per S-tag 1:1 hot standby resiliency.
- Two MAG-u nodes have two active FSGs.
- Two MAG-u nodes have one active FSG.
The difference between a MAG-u-level 1:1 model and an S-tag-level 1:1 model lies in the impact of multiple MAG-u failures. For example, compare the deployment where "north" and "south" back up each other and "east" and "west" back up each other without overlap. We assume each S-tag range is responsible for about 1/6th of the traffic.
- When two MAG-u nodes fail in the per S-tag mode, it always impacts 1/6th of traffic because each pair of MAG-u nodes is always uniquely responsible for one S-tag out of six. For example, if "north" and "south" fail, S-tag 4 completely fails.
- When two MAG-u nodes fail in the per-MAG-u mode, the impact depends on which nodes fail and that can either impact 0% or 50% of the traffic. For example, if both "north" and "west" fail, there is no lasting traffic impact because they do not back up each other. If both "south" and "north" fail, all traffic of the two S-tags covered by these MAG-u nodes fails.
This effect becomes stronger with more MAG-u nodes and S-tags to distribute. For example, in a model with 10 MAG-u nodes, the configuration can limit a failure of two MAG-u nodes to only affect about 2% of the traffic versus potentially 20% of the traffic if five 1:1 pairs are used.
This model makes the following assumptions on the aggregation model:
- A shared L2 broadcast domain must be available for all MAG-u nodes.
- A suitable granularity to differentiate UP groups must be available, such as S-tags in the example above.
- The MAG-u failures are unrelated. If the MAG-u failures happen in bulk (for example, because they are co-located), it can be better to make sure no co-located MAG-u nodes back up each other instead of to distribute resiliency as much as possible.
Fixed access with active/standby pseudowire access
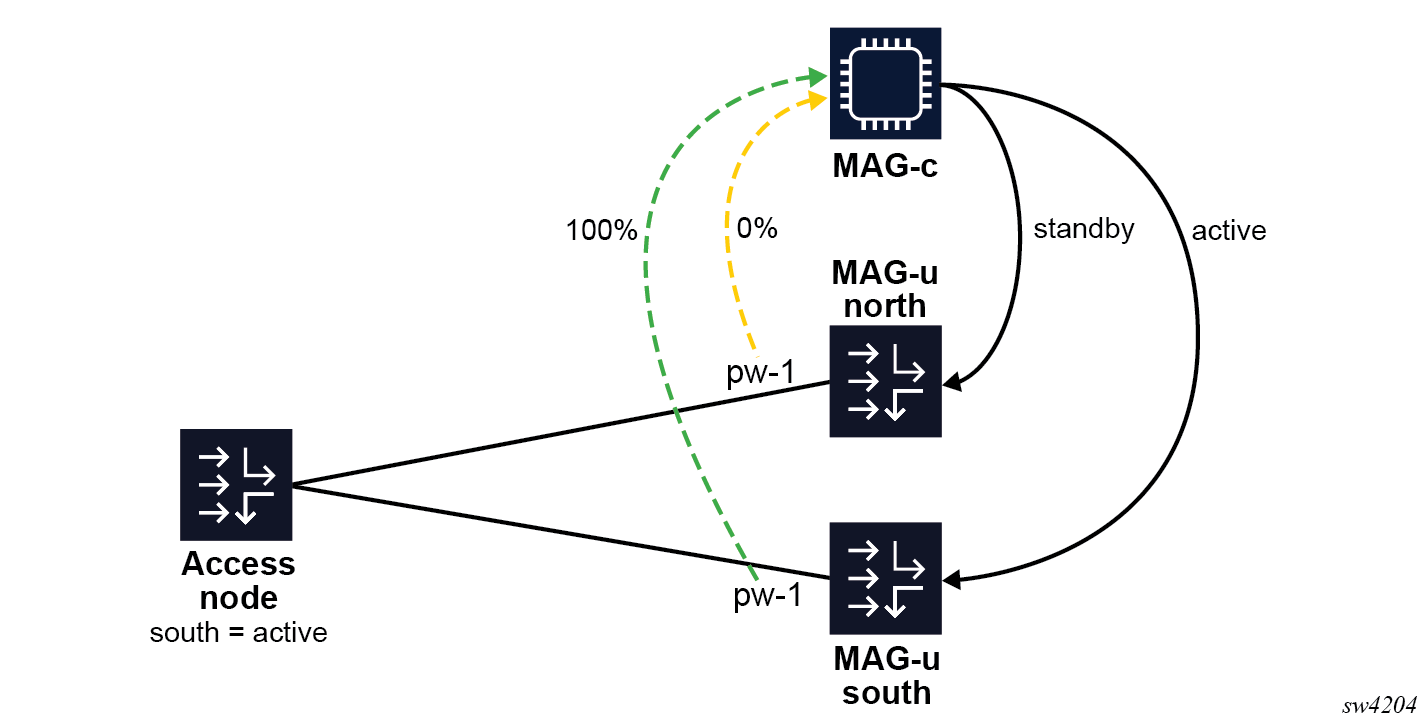
MAG-u resiliency is possible with active/standby pseudowire (A/S PW) access. The access network selects the active and standby PW of an A/S PW, and the MAG-u nodes must follow this decision.
The configuration of the FSG-based resiliency mechanism ensures that the FSG state follows the A/S state determined by the access node. This mechanism is modeled using UP groups as follows:
- The A/S PW pair is covered by a single UP group; that is, the Layer 2 access IDs representing the A/S PW cannot be present in any other UP group.
- The UP group covering the A/S PW pair cannot contain any other Layer 2 access IDs.
- The MAG-u signals to the MAG-c a Layer 2 access ID health of 0% or 100% , which corresponds to the PW being standby (0%) or active (100%) on that MAG-u. To configure this on a Nokia MAG-u, see Configuring an A/S PW port on the Nokia MAG-u.
- The UP group covering the A/S PW pair must not contain any configuration that triggers the MAG-c to enforce an A/S state in the access network; for example, the drain or preferred configuration.
- The linked FSG profile cannot monitor network health because that can lead to the MAG-c enforcing an A/S decision that does not correspond to the PW A/S state.
The following figure and configuration output show an example of a PW and the associated UP group configuration.
up-group "prefer-east"
    l2-access-id pw-1
    up "north"
    exit
    up "south"
    exit
no shutdownBecause the drain command is not supported in this setup, Nokia recommends performing the following procedure when maintenance on a MAG-u is required: Maintenance on a Nokia MAG-u in an A/S PW setup.
- The entire MAG-u has failed. The decision to switch over is correct. The A/S PW also performs a switchover.
- Only the PFCP path has failed (headless). The decision to switch over may be incorrect because the A/S PW state is independent of the PFCP path.
- When in headless mode, the MAG-u
must fully bring down the PW. This forces the access node to also switch over
because it perceives a failed MAG-u.
To configure this, see Bringing down the PW in headless conditions.Caution: If both MAG-u nodes of an A/S PW pair become headless, forwarding stops but the session state is retained.
- On the MAG-c, PFCP headless mode must be aligned with BFD to ensure the MAG-u and MAG-c go into headless mode at similar intervals. See Headless mode for more information.
- The MAG-u must be configured to move an FSG to standby whenever headless operations occur. See Moving an FSG to standby in headless mode to configure this.
Configuring an A/S PW port on the Nokia MAG-u
The basic SDP, PW port, and capture SAP configuration must be present.
-
Configure an operational group to monitor the PW port.
configure service oper-group -
Apply the operational group to the PW port.
configure pw-port oper-group -
Apply the operational group for health monitoring on the capture SAP created
for the PW port.
configure service vpls capture-sap pfcp up-resiliency monitor-oper-group -
Set the drop in health value to 100 in the context created in step 3. This
causes the reported health of the Layer 2 access ID to go from 100% to 0% when
the PW becomes standby on the MAG-u.
configure service vpls capture-sap pfcp up-resiliency monitor-oper-group health-drop - Optional:
Define a Layer 2 access ID alias to simplify the correlation of the A/S PWs on
two different MAG-u
nodes when provisioning UP groups on the MAG-c.
configure service vpls capture-sap pfcp l2-access-id-alias
Maintenance on a Nokia MAG-u in an A/S PW setup
Because the drain command is not supported in a MAG-u resiliency setup with A/S PW access, Nokia recommends performing the following procedure for MAG-u maintenance. For example, perform this procedure for upgrading the MAG-u or restarting the PFCP association.
Avoid performing maintenance on multiple MAG-u nodes in parallel. If multiple MAG-u nodes require maintenance, execute the procedure for each MAG-u one at a time.
-
Verify that no FSG changes are ongoing for FSGs related to this MAG-u;
for example, changes as a result of finalizing a maintenance procedure for
another MAG-u.
Execute the following command to list all FSGs and UP groups related to the MAG-u.
Execute the following command for each FSG listed in the output of the preceding command.show mobile-gateway pdn bng up
No changes are ongoing if the output indicates the following:show mobile-gateway pdn bng fsg- Standby Ready field displays yes
- Active Changing field displays no
- Current Hold-Off Delay field displays 0 msec
- Locked field displays no
-
On the MAG-u,
disable the PW port SDP.
configure pw-port sdp admin-state -
If a PFCP association restart is required, disable the PFCP association on the
MAG-u.
configure subscriber-mgmt pfcp association admin-state - Execute the required maintenance operations on the MAG-u.
- If a PFCP association restart was required in step 3, re-enable the PFCP association on the MAG-u.
-
Verify and wait until the MAG-c has synchronized all sessions.
On the MAG-c, execute the following command for all FSGs identified in step 1.
Synchronization is complete if the output displays the following:show mobile-gateway pdn bng fsg- Standby Ready field displays yes
- Active Changing field displays no
- Current Hold-Off Delay field displays 0 msec
- Locked field displays no
-
On the MAG-u,
re-enable the PW port.
configure pw-port sdp admin-state
Bringing down the PW in headless conditions
-
Configure an operational group to monitor the path between the MAG-u
and the MAG-c.
configure service oper-group -
Enable BFD for the configured operational group.
In the following context, use the interface-name and router-instance commands to match the interface used by PFCP, and use the dest-ip command to set the IP address that the MAG-c uses for PFCP.
configure service oper-group bfd-liveness -
For the configured operational group, set the hold up time equal to the PFCP
heartbeat interval and the hold down time greater than the BFD session recovery
time.
configure service oper-group hold-time up configure service oper-group hold-time down -
Enable BFD under the interface used for PFCP.
From the following list of commands, use only the commands that are relevant to the IP stack used for PFCP:
Although the transmit-interval, receive, and multiplier commands in the preceding contexts can be configured according to your needs, Nokia discourages sub-second failure detection to avoid aggressive switchovers upon minor interruptions.configure router interface ipv4 bfd configure router interface ipv6 bfd configure service vprn interface ipv4 bfd configure service vprn interface ipv6 bfd -
Set up the configured operational group for monitoring under the SDP linked to
the PW port. This causes the system to bring down the SDP and PW port when in
headless mode.
configure pw-port sdp monitor-oper-group -
Enable BFD assisted PFCP headless mode to align PFCP path management with the
BFD decision when in headless mode.
configure subscriber-mgmt pfcp association bfd-expedited-path-down
Moving an FSG to standby in headless mode
-
Create an FSG template on the MAG-u.
configure subscriber-mgmt up-resiliency fate-sharing-group-template -
In the configured FSG template on the MAG-u,
set the path restoration state to standby.
configure subscriber-mgmt up-resiliency fate-sharing-group-template path-restoration-state -
Apply the FSG template to the FSG on the MAG-c.
- If the configured FSG template name is "default" and the MAG-c does not specify any template, the template is automatically applied and no further configuration is needed.
- If the configured FSG template name is different from "default", perform the following substeps.
FWA MAG-u mesh
For fixed wireless access (FWA), there is a routed aggregation model between the UE, RAN, and the MAG-u. Consequently, each MAG-u in a single routed network can back up any other MAG-u in that same network. This allows for optimal spread of standby sessions and helps to minimize impact if a failure occurs. To achieve this, each MAG-u must be provisioned with as many FSGs as there are other MAG-u nodes. For an aggregation network with N MAG-u nodes, this means that each MAG-u is provisioned with N-1 FSGs for which it is active, for a total of N × (N-1) FSGs in the network. This forms a mesh of FSGs.
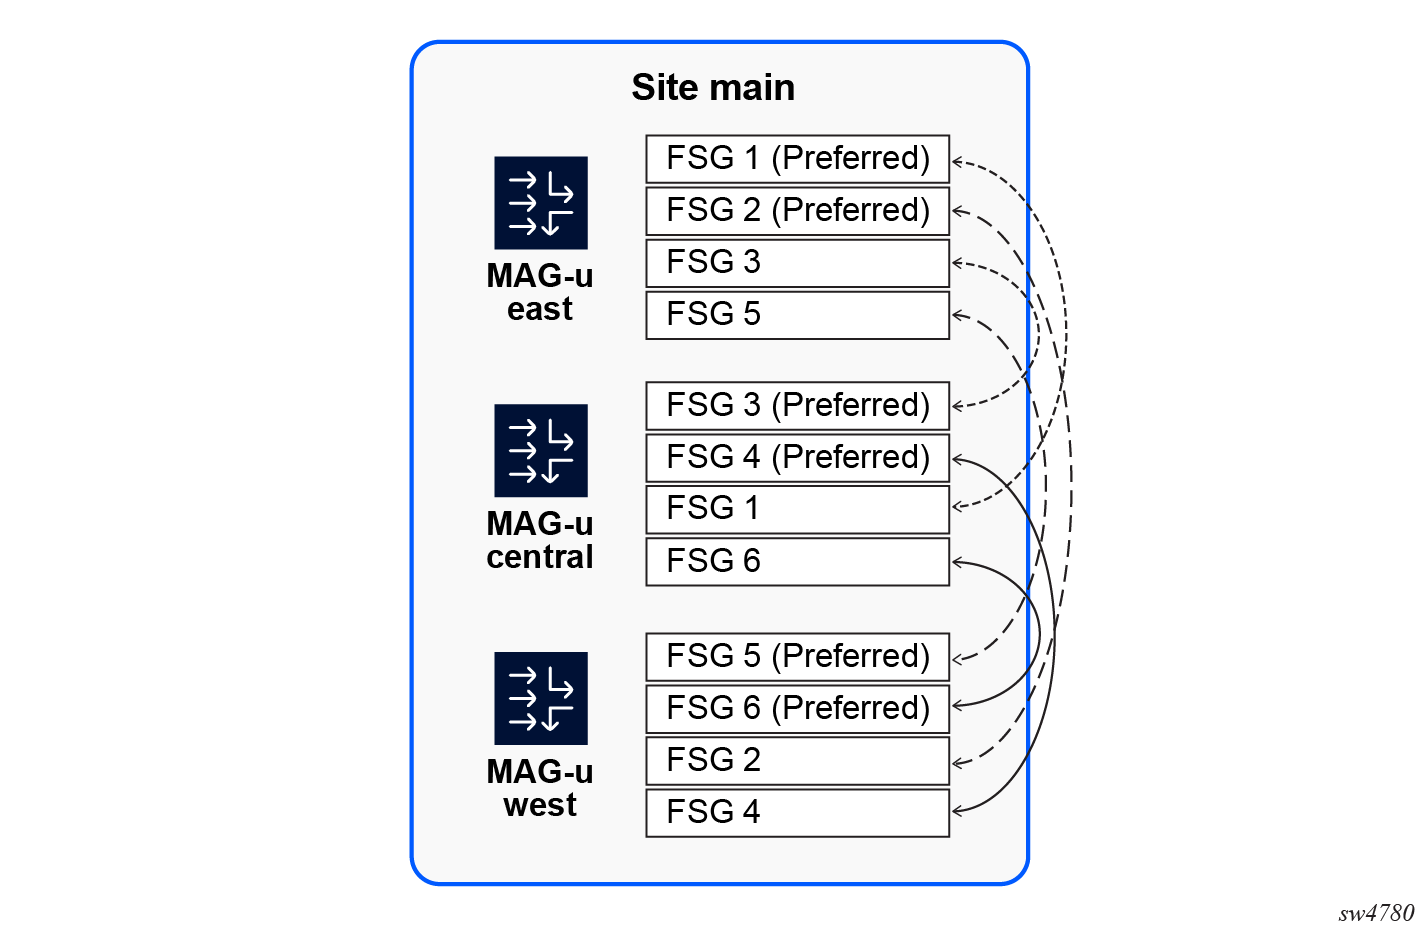
To provision such a mesh, see Provisioning an FWA MAG-u mesh.
Provisioning an FWA MAG-u mesh
-
Create a new UP group using the following command.
configure mobile-gateway pdn bng up-group -
Configure the FSG mode for the UP group to mesh-per-site
using the following command.
configure mobile-gateway pdn bng up-group fsg-mode mesh-per-site -
Configure all the MAG-u
nodes that are to be part of the mesh using the following command.
configure mobile-gateway pdn bng up-group up -
Create a new site within the UP group using the following command.
configure mobile-gateway pdn bng up-group siteNote: While site awareness itself is an optional feature (see Inter-site redundancy for FWA sessions for more information), the FSG mesh always needs at least one site to be configured. This allows easy migration to site awareness at a later time. -
Add all the MAG-u
nodes to the newly created site using the following command.
configure mobile-gateway pdn bng up-group site up -
Configure the GTP-u endpoint addresses to be assigned to the FSG using the
following commands.
For more information about GTP-u endpoint allocation per FSG, see Traffic steering parameters.configure mobile-gateway pdn bng up-group gtp-u-endpoints realm ipv4-range configure mobile-gateway pdn bng up-group gtp-u-endpoints realm ipv6-prefix -
Configure an FSG profile using the following command.
configure mobile-gateway profile bng fsg-profile -
In the configured FSG profile, use the following command to enable the network
realms that require health monitoring, for example the GTP-u endpoint realms
(S1-u/N3) and the network-facing realms (SGi/N6).
configure mobile-gateway profile bng fsg-profile health-calculation network-realmNote: This instructs the MAG-c to take only the health of that network realm into account. It is also necessary to configure the MAG-u to signal a sensible health value for the configured realms. See the 7750 SR and VSR BNG CUPS User Plane Function Guide for more information. -
Configure any other FSG parameters, and when finished, apply that FSG profile
to the UP group using the following command.
configure mobile-gateway pdn bng up-group fsg-profile -
Enable the UP group using the following command.
configure mobile-gateway pdn bng up-group no shutdown -
Investigate the state of the created UP group by executing the following
command with the name of the created UP group as a parameter.
show mobile-gateway pdn bng up-groupThis command lists all the configured MAG-u nodes and N*(N-1) FSGs, where N is the number of MAG-u nodes. For each MAG-u, the following information should be stated:- health of 100
- list N-1 FSGs for which the MAG-u is active
- list N-1 FSGs for which the MAG-u is on standby
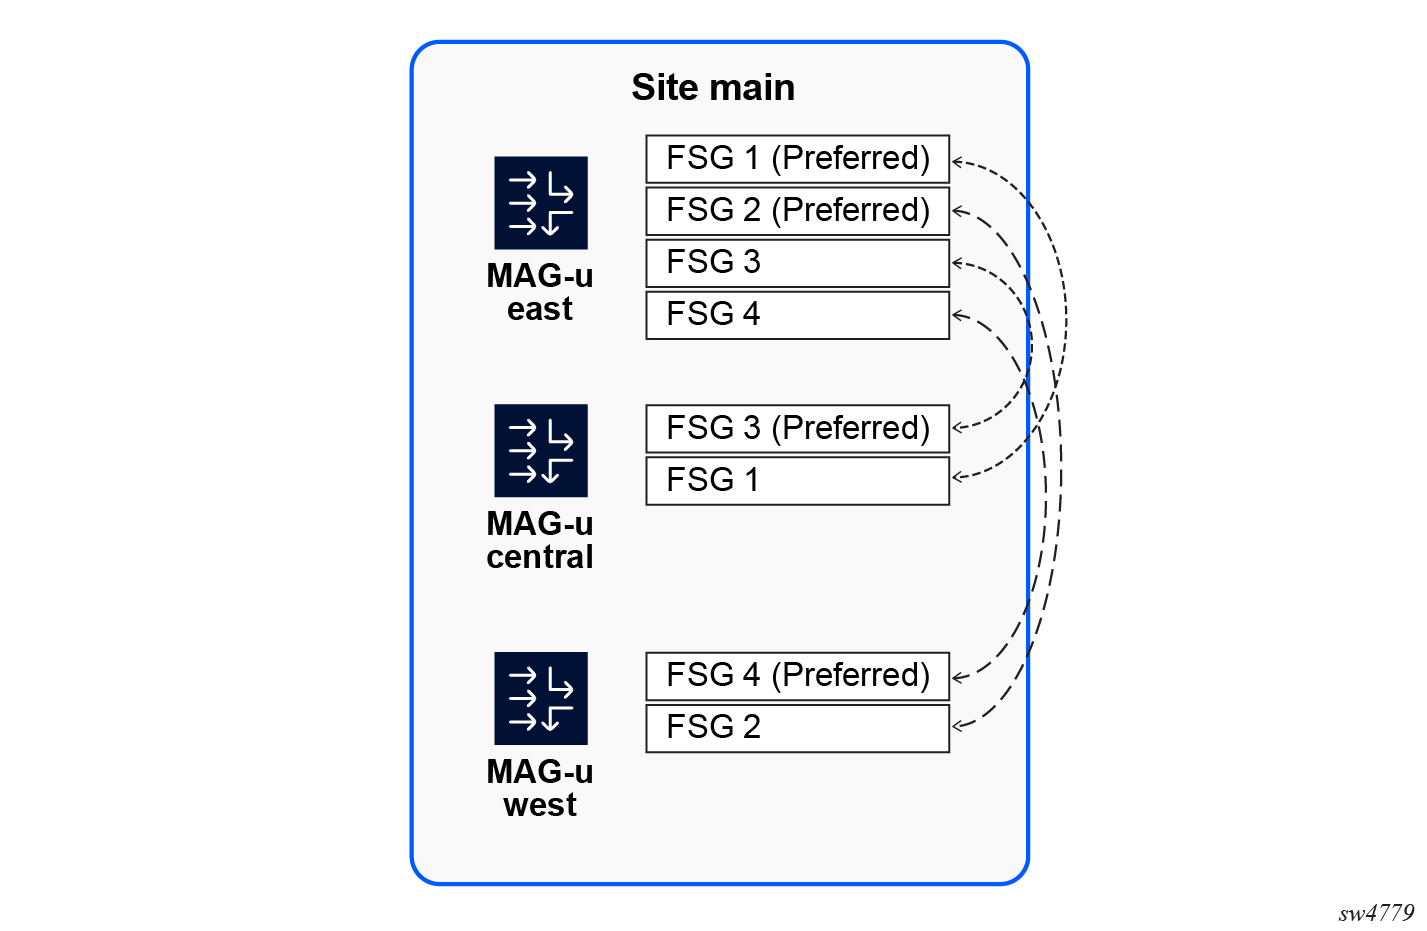
The following example output displays the properties of the created mesh.Mesh propertiesA:MAG-c>show>mobile-gateway>pdn>bng>up-group# "fwa_mesh" =============================================================================== Up-Group 'fwa_mesh' =============================================================================== PDN gateway : 1 Description : (Not Specified) Admin State : up FSG Profile : fwa Default Standby Type : hot ------------------------------------------------------------------------------- FSG Active UP Standby UP Sessions Hold-Off ------------------------------------------------------------------------------- 2 up-east up-central (ready) 0 0 3 up-central up-east (ready) 0 0 4 up-west up-central (ready) 0 0 5 up-central up-west (ready) 0 0 6 up-west up-east (ready) 0 0 7 up-east up-west (ready) 0 0 ------------------------------------------------------------------------------- No. of FSGs: 6 ------------------------------------------------------------------------------- ------------------------------------------------------------------------------- UP Pref Drain Health Fsg Role ------------------------------------------------------------------------------- up-central (192.0.2.13) no no 100 2 Std 3 Act 4 Std 5 Act up-east (192.0.2.11) no no 100 2 Act 3 Std 6 Std 7 Act up-west (192.0.2.12) no no 100 4 Act 5 Std 6 Act 7 Std ------------------------------------------------------------------------------- No. of UPs: 3 ------------------------------------------------------------------------------- ------------------------------------------------------------------------------- Site Rebalance ------------------------------------------------------------------------------- main no ------------------------------------------------------------------------------- No. of Sites: 1 ------------------------------------------------------------------------------- ===============================================================================This output suggests that:- Six FSGs are created, following the N × (N-1) = 3 × 2 formula.
- Each FSG has two associated MAG-u nodes.
- Each MAG-u is 100% healthy.
- Each MAG-u pair has two FSGs, for example, up-west and up-east share FSGs six and seven, where up-west is active (preferred) for FSG six and up-east is active (preferred) for seven.
-
After verifying the UP group is correctly provisioned, assign FWA sessions to
the UP group and site using the following command.
configure mobile-gateway profile authentication-database entry fixed-wireless-access up-groupMesh generation in a UP group with three MAG-u nodesA:MAG-c>config>mobile-gateway>pdn>bng# info ---------------------------------------------- up-group "fwa_mesh" fsg-mode mesh-per-site fsg-profile "fwa" gtp-u-endpoints realm "to_ran" ipv4-range 192.0.2.50 192.0.2.100 ipv6-prefix 2001:db8::/64 exit exit up "up-central" exit up "up-east" exit up "up-west" exit site "main" up "up-central" up "up-east" up "up-west" exit no shutdown exit ----------------------------------------------
Inter-site redundancy for FWA sessions
For information about how to configure additional sites and assign MAG-u nodes to them, see Creating sites with assigned MAG-u nodes.
The benefit of using multiple sites within a UP group (instead of multiple UP groups), is it achieves inter-site redundancy. The MAG-c tracks the number of failed MAG-u nodes for each site. If the number of failed MAG-u nodes meets or exceeds a provisioned threshold, the MAG-c stops assigning sessions to FSGs within the failed site. Instead, it assigns sessions directly to MAG-u nodes in other sites, bypassing FSG functionality.
Creating sites with assigned MAG-u nodes
-
Add the MAG-u
nodes to the UP group using the following command.
configure mobile-gateway pdn bng up-group up -
Create a site within the UP group using the following command.
configure mobile-gateway pdn bng up-group site -
Add the MAG-u
nodes to the newly created site using the following command.
configure mobile-gateway pdn bng up-group site up -
Configure the behavior of inter-site failover using the following
command.
configure mobile-gateway pdn bng up-group site inter-site-failoverDepending on your preferences, use the following options:- failed-up-thresholdA site is declared as failed when the number of failed MAG-u nodes within it is bigger than or equal to the number of MAG-u nodes in the site or the value set with this command, whichever is smaller. A MAG-u itself is declared as failed based on its health signaling and the failure threshold configured with the following command.
See MAG-u health determination for more information.configure mobile-gateway profile bng fsg-profile health-calculation failure-threshold - backup-up
When a site fails, the MAG-c assigns a session to any non-failed MAG-u within all other sites by default. This command overrides this function and instead provides an explicit list of backup MAG-u nodes to be considered.
- pool-overrides
The commands in this context apply to sessions that were originally assigned to a site that failed, and are now installed on a MAG-u of this site. Instead of using the pools assigned to the session during authentication, the pools in this context are used. This can be useful, for example, if dedicated pools are used per site and the original pools are not available on this site.
- failed-up-threshold
Anti-affinity to avoid FSG creation
configure mobile-gateway pdn bng up-group up anti-affinity-labelConfiguration of single shared affinity label
The MAG-c does not create any FSGs between MAG-u nodes with the same label. The following example shows a single affinity label shared between the MAG-u nodes "up-east" and "up-west".
A:MAG-c>config>mobile>pdn>bng# info
----------------------------------------------
up-group "fwa_mesh"
fsg-mode mesh-per-site
fsg-profile "fwa"
gtp-u-endpoints
realm "to_ran"
ipv4-range 192.0.2.50 192.0.2.100
ipv6-prefix 2001:db8::/64
exit
exit
up "up-central"
exit
up "up-east"
anti-affinity-label "avoid_fsg"
exit
up "up-west"
anti-affinity-label "avoid_fsg"
exit
site "main"
up "up-central"
up "up-east"
up "up-west"
exit
no shutdown
exit
----------------------------------------------FWA mesh information for UP groups
The output of the following example, and Mesh anti-affinity, display the result, which is that two less FSGs have been created and there is no FSG present that contains both those MAG-u nodes.
A:MAG-c>show>mobile-gateway>pdn>bng>up-group# "fwa_mesh"
===============================================================================
Up-Group 'fwa_mesh'
===============================================================================
PDN gateway : 1
Description : (Not Specified)
Admin State : up
FSG Profile : fwa
Default Standby Type : hot
-------------------------------------------------------------------------------
FSG Active UP Standby UP Sessions Hold-Off
-------------------------------------------------------------------------------
8 up-east up-central (ready) 0 0
9 up-central up-east (ready) 0 0
10 up-west up-central (ready) 0 0
11 up-central up-west (ready) 0 0
-------------------------------------------------------------------------------
No. of FSGs: 4
-------------------------------------------------------------------------------
-------------------------------------------------------------------------------
UP Pref Drain Health Fsg Role
-------------------------------------------------------------------------------
up-central (192.0.2.13) no no 100 8 Std
9 Act
10 Std
11 Act
up-east (192.0.2.11) no no 100 8 Act
9 Std
up-west (192.0.2.12) no no 100 10 Act
11 Std
-------------------------------------------------------------------------------
No. of UPs: 3
-------------------------------------------------------------------------------
-------------------------------------------------------------------------------
Site Rebalance
-------------------------------------------------------------------------------
main no
-------------------------------------------------------------------------------
No. of Sites: 1
-------------------------------------------------------------------------------
===============================================================================
Session rebalance and revert
- New sessions are not installed on a subset of FSGs because the associated MAG-u nodes failed. This leads to a load imbalance across FSGs.
- New sessions ignore load-based FSG selection but are steered to specific FSGs for a number of possible reasons (see Session-to-FSG mapping and load-balancing for more information). This leads to a load imbalance across FSGs.
- New sessions are installed on another site because of site failures (see Inter-site redundancy for FWA sessions for more information). This leads to sessions not being present on the preferred site.
To resolve this, the MAG-c offers revert and rebalancing functions. Both these functions disconnect specific sessions to resolve the sub-optimal session distribution. The sessions are signaled with NAS cause code #39 (Reactivation Requested) on 5G systems and with GTP cause value #8 (Reactivation Requested) on 4G systems, to trigger the UE to immediately reconnect.
- revert
The revert function disconnects all sessions that should be set up on an FSG of a specific target site but are active on a MAG-u from another site.
Use the following command to trigger a revert action in the specified site.clear mobile-gateway pdn bearer-context up-group target-site action revertNote: See the MAG-c CLI Reference Guidefor the complete list of available parameters for the clear command. - rebalance
The rebalance function periodically disconnects a number of sessions in the specified target site until the difference between the least loaded MAG-u and the most loaded MAG-u is less than or equal to the specified difference. If no difference is specified, it defaults to 5%.
Use the following command to trigger the rebalance action in the specified site.clear mobile-gateway pdn bearer-context up-group target-site action rebalanceNote: See the MAG-c CLI Reference Guidefor the complete list of available parameters for the clear command.To see if a rebalance action is in progress, use the following command, with or without the detail parameter.show mobile-gateway pdn bng up-groupFor example:A:MAG-c>show>mobile-gateway>pdn>bng>up-group# "fwa_mesh" ... ------------------------------------------------------------------------------- Site Rebalance ------------------------------------------------------------------------------- main yes -------------------------------------------------------------------------------If you add thedetail parameter, you can also see the current loop and the max loops that the system executes.
For example:A:MAG-c>show>mobile-gateway>pdn>bng>up-group# "fwa_mesh" detail ... ------------------------------------------------------------------------------- Site main ------------------------------------------------------------------------------- up-east (192.0.2.11) up-west (192.0.2.12) up-central (192.0.2.13) Inter Site Failover Failed UP Threshold : 8 Rebalance Ongoing : yes Current Loop : 6 Max Loops : 50 ------------------------------------------------------------------------------- - cancel-rebalanceTo cancel an ongoing rebalance action, use the following command.
clear mobile-gateway pdn bearer-context up-group target-site action cancel-rebalance - time-of-dayOptionally, it is possible to set up the MAG-c to automatically execute both revert and rebalance actions at a specified time of day using the following command.
configure mobile-gateway profile bng fsg-profile auto-revert-rebalance time-of-day
All the commands related to the MAG-c revert and rebalancing functions are subject to a deletion rate. Nokia recommends to use the lowest possible deletion rate to minimize impact on other call flows.
configure mobile-gateway pdn session-deletion-rateAdding a MAG-u to an existing UP group for FWA sessions
-
Add the MAG-u to
the UP group using the following command.
configure mobile-gateway pdn bng up-group upNote: When configuring an IPv4 address, make sure there are sufficient addresses in the IPv4 ranges configured with the gtp-u-endpoints command; otherwise, the system may reject adding a new MAG-u. This is not the case when configuring IPv6 addresses, because a prefix is used instead of a range. -
Apply any configuration, such as an anti-affinity-label, to the MAG-u.
Note: Most MAG-u configurations cannot be changed after adding the MAG-u to a site.
-
Add the MAG-u to a
site using the following command.
configure mobile-gateway pdn bng up-group site up
Removing a MAG-u from an existing UP group
-
Remove the MAG-u
from the site by using the following command.
configure mobile-gateway pdn bng up-group site no up -
Remove the MAG-u
from the UP group by using the following command.
configure mobile-gateway pdn bng up-group no up
clear mobile-gateway pdn bearer-context up-group target-site action clear-lingering-fsgsMaintenance on a Nokia MAG-u
Nokia recommends performing the following procedure for MAG-u maintenance where session stability cannot be guaranteed; for example, for upgrading the MAG-u or restarting the PFCP association.
Avoid performing maintenance on multiple MAG-u nodes in parallel. If multiple MAG-u nodes require maintenance, execute the procedure for each MAG-u one at a time.
In a geo-redundant MAG-c deployment, you must apply all configuration commands first on the standby node, and then the active node.
Execute the admin save command after each configuration step.
-
Verify that no FSG changes are ongoing for FSGs related to the MAG-u;
for example, changes as a result of finalizing a maintenance procedure for
another MAG-u.
List all FSGs and UP groups related to the MAG-u.
Execute the following command for each FSG listed in the output of the preceding command.show mobile-gateway pdn bng up
No changes are ongoing if the output indicates the following:show mobile-gateway pdn bng fsg- Standby Ready field displays yes
- Active Changing field displays no
- Current Hold-Off Delay field displays 0 msec
- Locked field displays no
If any of the Drain fields display yes, a MAG-u is set to drain mode. This may indicate that a maintenance procedure for another MAG-u is ongoing. Verify if this is intended and, if necessary, correct by completing the maintenance procedure for the specific MAG-u. -
Enable the drain mode for the MAG-u
in all UP groups identified in step 1.
configure mobile-gateway pdn bng up-group up drain -
Verify that the MAG-u
is no longer active in any FSG and that the FSGs are stable.
List the MAG-u state in all FSGs.
The MAG-u is no longer active if the Role column is different from Act for all entries in the list. If this is not the case, wait until the value in the Role column is different from Act for all entries. Periodically execute the preceding command to check this information.show mobile-gateway pdn bng upExecute the following command for each FSG identified in step 1.
No changes are ongoing if the output indicates the following:show mobile-gateway pdn bng fsg- Active Changing field displays no
- Current Hold-Off Delay field displays 0 msec
- Locked field displays no
- Execute the required maintenance operations (for example, an upgrade or PFCP Association Restart) on the MAG-u.
- After the MAG-u maintenance operations have fully completed, perform step 3 to verify that the FSGs are stable.
-
Disable the drain mode for the MAG-u
in all its related UP groups.
configure mobile-gateway pdn bng up-group up no drain
Fate sharing groups
Fate sharing groups (FSGs) are groups of sessions on which resiliency operations are performed. FSGs are automatically created based on configured UP groups. The FSGs are provisioned via the UP group.
When an FSG is created, the MAG-c performs the following operations:
- Map new sessions to the FSG (see Session-to-FSG mapping and load-balancing).
- Determine traffic management parameters to attract traffic only to the MAG-u that serves the specific FSG (see Traffic steering parameters).
- Determine an aggregated health value for each MAG-u in the FSG.
- Upon MAG-u state and health changes, reselect an active and standby MAG-u for the FSG. Any change triggers this reselection, which guarantees that no state change is lost. In many cases, the MAG-c selects the same active and standby MAG-u as previously.
- Upon any active/standby change, update the FSG state on the MAG-u and, if necessary, update the session state on the MAG-u.
FSGs follow an intent-based processing model. The configuration specifies the edge conditions of resiliency behavior, expressing its intent. For example, the configuration specifies whether switchovers should be revertive and whether there is a preferred MAG-u. The MAG-c monitors multiple parameters and, if necessary, changes active/standby decisions to better match the intent. The MAG-c may execute multiple subsequent FSG changes to accomplish this.
Session-to-FSG mapping and load-balancing
When setting up a fixed access session, the MAG-c uses the MAG-u ID, the Layer 2 access ID, and the VLAN ranges of the triggering IBCP packet to look up a UP group. If a UP group contains this set of parameters, the MAG-c links the session automatically to the FSG created for that UP group.
configure mobile-gateway profile authentication-database entry fixed-wireless-access- If the mapped site fails, the session is not assigned to an FSG; instead, it is set up in a non-resilient way on a MAG-u in another site (see Inter-site redundancy for FWA sessions for more information). In this case, the same logic applies to the subsequent criteria, but a direct MAG-u is chosen instead of an FSG.
- In some cases, session setup parameters are taken into account to prefer a
specific FSG or set of FSGs. In such cases, a specific FSG is selected or the
number of eligible FSGs is reduced. For example:
- When a second session of a UE is set up, the MAG-c prefers the same FSG as in the previous session.
- When a session restarts and the held IP is recovered (see Session lifetime and held addresses), the MAG-c prefers the FSG that holds the ODSA micro-net for that held IP address.
- When a session is started with a static IP, and unnumbered interfaces are not used, the MAG-c prefers the FSG that holds the ODSA micro-net for that static IP address.
- When a preferred MAG-u is provisioned for a session, the MAG-c prefers FSGs that are preferred for that MAG-u.
- When both the active and standby MAG-u nodes fail for an FSG, the FSG is excluded from selection.
- The least loaded FSG is chosen, where load is based on the signaled load of the
preferred MAG-u
for that FSG. To enable learning load from the MAG-u,
use the following
command.
configure mobile-gateway pdn pfcp-load-control enable-pfcp-load-control - If all else is equal, the MAG-c distributes sessions evenly over the remaining FSGs.
Traffic steering parameters
- associates unique uplink and downlink parameters with each FSG
- signals those parameters to the MAG-u as part of creating the FSG when that MAG-u is selected as active or standby MAG-u for that specific FSG
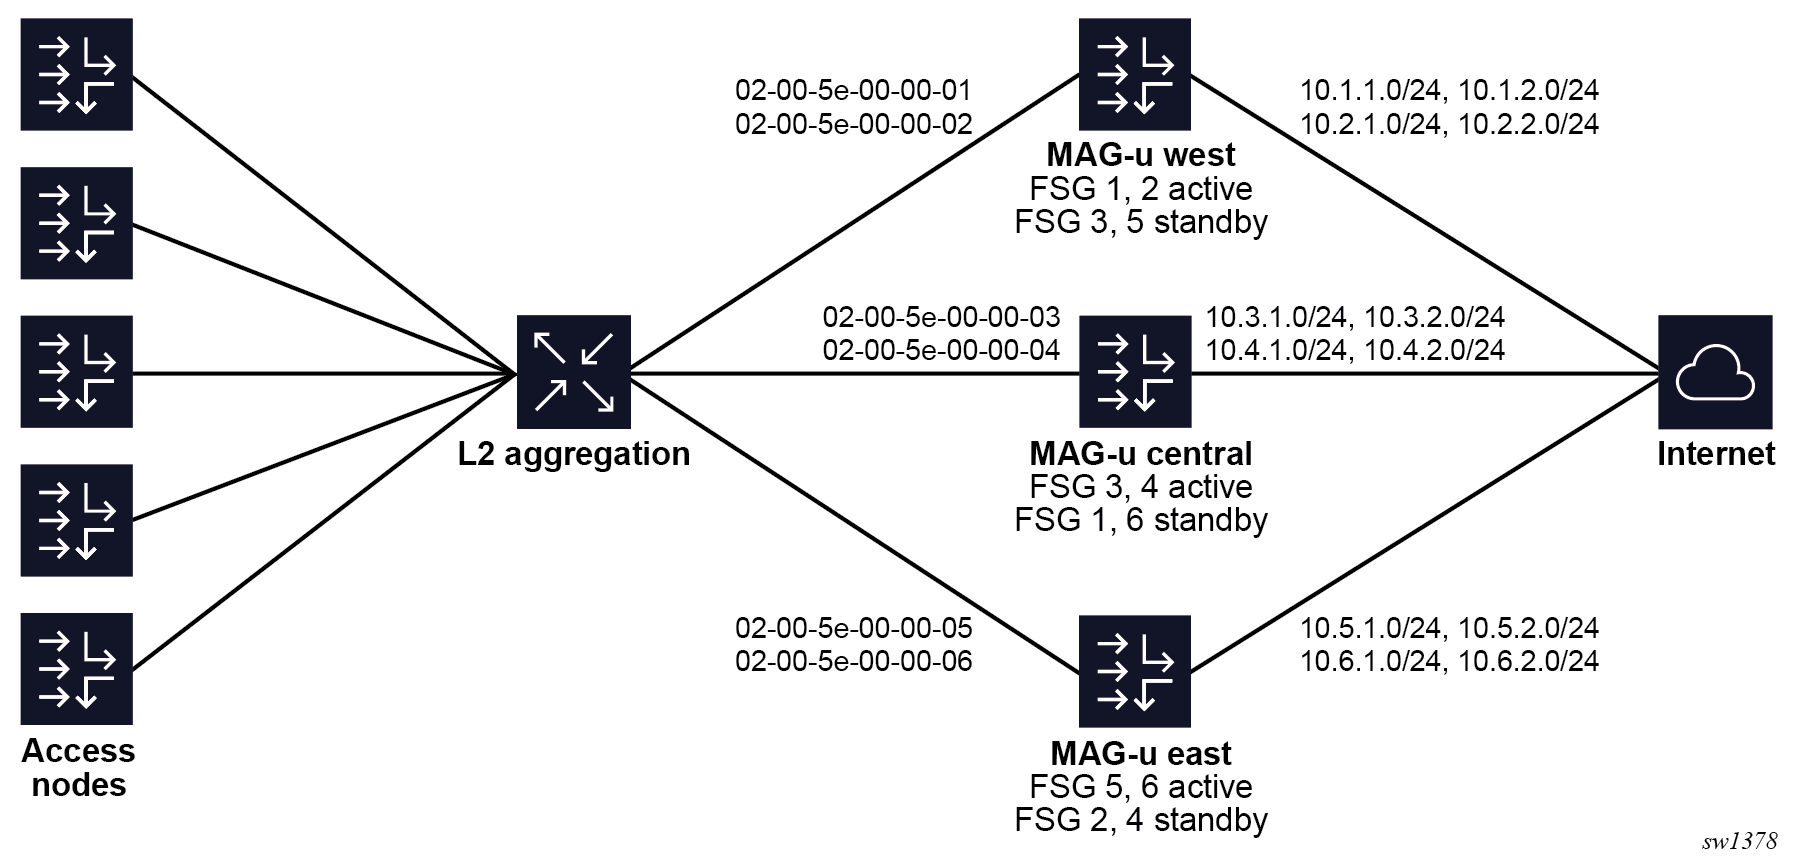
ODSA allocates a unique set of per-FSG subnets (micro-nets). Because the subnets are unique per FSG, the active MAG-u can announce these subnets. To achieve the uniqueness, a session that is linked to an FSG passes the FSG as an allocation context to ODSA. ODSA automatically makes the micro-nets unique in that context.
Fixed access
configure mobile-gateway profile bng fsg-profile mac-prefix-
FSG 1
MAC 02-00-5e-00-00-01
session subnet 10.1.1.0/24
session subnet 10.1.2.0/24
-
FSG 2
MAC 02-00-5e-00-00-02
session subnet 10.2.1.0/24
session subnet 10.2.2.0/24
-
FSG 3
MAC 02-00-5e-00-00-03
session subnet 10.3.1.0/24
session subnet 10.3.2.0/24
-
FSG 4
MAC 02-00-5e-00-00-04
session subnet 10.4.1.0/24
session subnet 10.4.2.0/24
-
FSG 5
MAC 02-00-5e-00-00-05
session subnet 10.5.1.0/24
session subnet 10.5.2.0/24
-
FSG 6
MAC 02-00-5e-00-00-06
session subnet 10.6.1.0/24
session subnet 10.6.2.0/24
FWA
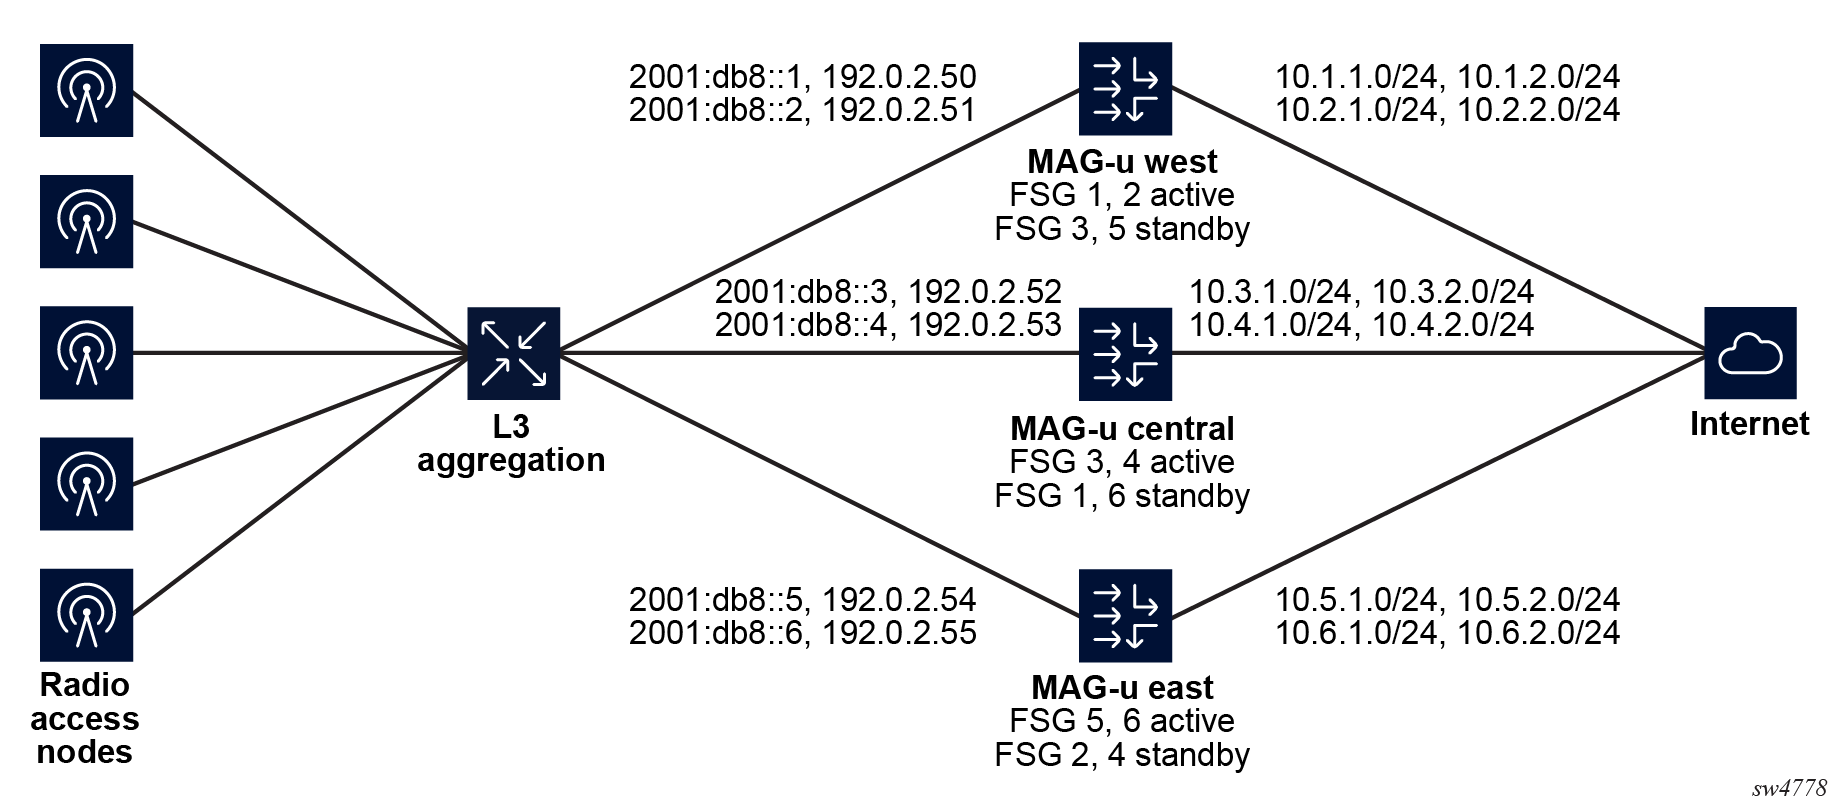
configure mobile-gateway pdn bng up-group gtp-u-endpoints realm ipv4-range
configure mobile-gateway pdn bng up-group gtp-u-endpoints realm ipv6-prefix- If an IPv4 range is configured, an address from that range is assigned to the FSG.
- If an IPv6 prefix is configured, the FSG ID is directly encoded in the last 16 bits of the IPv6 prefix to create a unique /128 IPv6 address.
configure mobile-gateway pdn s11 interface gtp-c interface-realm
configure mobile-gateway pdn s5 interface gtp-c interface-realm
configure mobile-gateway pdn sba-server-services nsmf-pdusession n3-interface-realm-
FSG 1
GTP-u endpoint IPv6 2001:db8::1
GTP-u endpoint IPv4 192.0.2.50
session subnet 10.1.1.0/24
session subnet 10.1.2.0/24
-
FSG 2
GTP-u endpoint IPv6 2001:db8::2
GTP-u endpoint IPv4 192.0.2.51
session subnet 10.2.1.0/24
session subnet 10.2.2.0/24
-
FSG 3
GTP-u endpoint IPv6 2001:db8::3
GTP-u endpoint IPv4 192.0.2.52
session subnet 10.3.1.0/24
session subnet 10.3.2.0/24
-
FSG 4
GTP-u endpoint IPv6 2001:db8::4
GTP-u endpoint IPv4 192.0.2.53
session subnet 10.4.1.0/24
session subnet 10.4.2.0/24
-
FSG 5
GTP-u endpoint IPv6 2001:db8::5
GTP-u endpoint IPv4 192.0.2.54
session subnet 10.5.1.0/24
session subnet 10.5.2.0/24
-
FSG 6
GTP-u endpoint IPv6 2001:db8::6
GTP-u endpoint IPv4 192.0.2.55
session subnet 10.6.1.0/24
session subnet 10.6.2.0/24
MAG-u health determination
- When the PFCP path between the MAG-c and the MAG-u
is down or in headless mode, the health value is -1 (unavailable).Note: If a PFCP association is not set up, the MAG-u is operationally not part of the UP group and has no health.
- When the following command is set to true, the health value is -1
(unavailable).
configure mobile-gateway pdn bng up-group up drain - In all other cases, the health value is based on an aggregation of the operational statuses received from the MAG-u.
The MAG-u can signal the following operational status values to the MAG-c:
- per Layer 2 access IDA percentage value per Layer 2 access ID indicates the current forwarding capacity compared to the full forwarding capacity. For example, if the Layer 2 access ID represents a LAG with five members where one member failed, the expected capacity is 80%.Note: The per Layer 2 access ID status value is not used for FWA MAG-u resiliency, where network instance health is also used toward the access.
- per Layer 3 service (also known as network instance or network realm)
A binary connectivity status per Layer 3 service indicates whether the Layer 3 network is reachable or not (connected or isolated). A Nokia MAG-u additionally augments this value with a percentage value to cover partial failures. The MAG-c uses the more detailed percentage value if available; otherwise, the MAG-c interprets the binary connectivity status as 100% for the connected state and 0% for the isolated state.
Not all status values of a single MAG-u apply to a specific FSG. For example, a UP group that only covers a single Layer 2 access ID is not impacted by any other Layer 2 access ID status. The MAG-c determines the applicable status values as follows:
- By default, the MAG-c uses for the aggregation all Layer 2 access IDs configured for the MAG-u in
the UP group. The following commands configure the L2 access
IDs.
configure mobile-gateway pdn bng up-group l2-access-id configure mobile-gateway pdn bng up-group up l2-access-id - The MAG-c can exclude configured Layer 2 access IDs from the health calculation. This
prevents the MAG-c from automatically setting the health value to 0 if the MAG-u does
not or cannot provide a status value for Layer 2 access IDs. The following command
specifies whether to include L2 access IDs and is enabled by
default.
configure mobile-gateway profile bng fsg-profile health-calculation include-l2-access-idsNote: For FWA MAG-u resiliency, no Layer 2 access ID is configured in the UP group and no Layer 2 access ID health is tracked independent of this configuration. - The MAG-c tracks a list of configured network realms for health aggregation. The following
command configures the tracked network
realms.
configure mobile-gateway profile bng fsg-profile health-calculation network-realm
configure mobile-gateway profile bng fsg-profile health-calculation aggregation-modeThe options for the aggregation mode are:
- lowest
This mode sets the per-MAG-u health to the lowest value of any Layer 2 access ID and network realm value. A single failure aggressively decreases the health.
- average
This option sets the per-MAG-u health to the arithmetic mean of all Layer 2 access ID and network realm values. A single failure less aggressively impacts the health.
If the MAG-u does not signal a status value for a Layer 2 access ID or network realm that is configured to be tracked, the MAG-c does not count that entity in the aggregation calculation.
configure mobile-gateway profile bng fsg-profile health-calculation failure-thresholdThe MAG-c maintains a special not-ready indicator for the current standby MAG-u. This indicator is set in the following conditions:
- The MAG-u changes to standby, independent of its previous state or health.
- The MAG-u health becomes unavailable (-1).
The MAG-c removes the not-ready indicator each time an FSG change successfully completes (see Active/standby change or switchover) and the health of the MAG-u at that time is 0% or higher.
The MAG-c avoids making a standby MAG-u with the not-ready indicator active unless it has no other choice; for example. when the PFCP association for the active MAG-u is released. This mechanism gives a recovered or new standby MAG-u a chance to go through one FSG change sequence to reinstall all the hot standby sessions before it can be made active.
The MAG-c can put a MAG-u in a lockout state for an FSG. When a MAG-u is in the lockout state, it cannot be made active or standby. Contrary to the other health values, the lockout state is intended to recover from hard failures where it is important that all FSG and related session state is removed from the MAG-u before it is considered active or standby again. See MAG-u lockout for more information.
The following table provides an overview of the states that are kept for MAG-u nodes that have an active association and that are linked to at least one FSG.
| State | Description | Sources |
|---|---|---|
| health |
A value between 0% and 100% or the special value -1 (unavailable) Indicates the health of the MAG-u |
Aggregation of the per-logical-port and per-network-realm health reports from the MAG-u PFCP path management state (for example, headless). The drain mode configured with the following
command.
|
| failed indicator |
An indicator that considers the MAG-u failed if its health is less than the failure threshold Enables switchovers in more restrictive (for example, non-revertive) scenarios |
Based on the health state and the threshold configured with the
following
command. |
| not-ready indicator |
An indicator on the standby MAG-u that does not have all hot standby sessions installed Kept until the standby MAG-u has installed the hot standby sessions |
Set for each new standby MAG-u or a standby MAG-u whose health becomes unavailable (-1). Removed after the first successful FSG change when the health is 0% or higher. |
| lockout |
A failure state in which the MAG-u cannot be made active or standby Kept until the MAG-u is no longer active or standby and a lockout timer has expired |
Applied automatically for multiple failure scenarios, see MAG-u lockout for more information. |
Active/standby selection triggers
- recovery (for example, health up)
- degradation (for example, health down)
- starts a hold timer
- waits for the hold timer expiry
- triggers the active/standby selection
configure mobile-gateway profile bng fsg-profile active-standby-selection hold-off-on-recovery
configure mobile-gateway profile bng fsg-profile active-standby-selection hold-off-on-degradation- A health increase triggers a recovery hold timer of 5 s.
- A health decrease triggers the default degradation hold timer of 0 ms.
When a trigger occurs while an active/standby change is in progress, the MAG-c ignores the hold timer of the new trigger and re-evaluates the active/standby selection as soon as the in-progress change completes.
The MAG-c treats the following events as a trigger:
- Any health increase acts as a recovery trigger. The cause of the health increase is irrelevant and may be because of headless recovery, change of the drain configuration of the MAG-u, or a MAG-u health report.
- Any health decrease acts as a degradation trigger.
- A PFCP association setup acts as a recovery trigger, except if it is the first MAG-u set up for the FSG.
- A PFCP association release acts as a degradation trigger, except if it is already the active or standby MAG-u.
- A MAG-u lockout acts as a degradation trigger.
- A MAG-u lockout removal acts as a recovery trigger.
- The intended FSG state not matching the current FSG state after an FSG event acts as a recovery trigger (see Active/standby change or switchover).
The following exceptional triggers bypass the normal reselection mechanism because of their big impact:
- The setup of the first PFCP association for an FSG triggers an immediate reselection. The MAG-c does not wait for the expiry of the recovery hold timer. If the PFCP association being set up is not the first association, it acts as a health increase and the MAG-c starts the recovery hold timer.
- A PFCP association release for the active or standby MAG-u triggers an immediate reselection, bypassing any hold timers. If an active/standby change is already in progress, the ongoing change is completed first. A PFCP association release for any other MAG-u acts as a health decrease and the MAG-c starts the degradation hold timer.
- If all MAG-u nodes become headless, the MAG-c does not trigger any reselection. As soon as the first MAG-u
recovers from headless, the MAG-c ignores the recovery hold timer but starts a timer based on the configured
path-management heartbeat intervals. The MAG-c triggers reselection of all MAG-u
nodes when one of the following occurs:
- the timer based on the configured path-management heartbeat intervals expires
- 5 s have passed after the last MAG-u recovered
Note: This mechanism ensures that after a full connectivity failure, all MAG-u nodes have time to recover the PFCP communication. It makes sure that the MAG-c makes decisions based on the full set of recovered MAG-u nodes and not on the first recovered MAG-u nodes.
Active/standby selection
When an active/standby selection trigger occurs, the MAG-c re-evaluates the selection of the active and standby MAG-u nodes for an FSG. If only one MAG-u with an active association is available, that MAG-u is always selected as the active MAG-u. Otherwise, both the active and standby MAG-u can be reselected.
Replacing the active MAG-u with the current standby MAG-u works in one of the following basic modes:
- revertive
The current standby MAG-u can be selected as the active MAG-u even if the active MAG-u did not fail. The conditions in which the standby MAG-u can become the active MAG-u are the same as the conditions to select the standby MAG-u. Additionally, the standby MAG-u cannot have the not-ready indicator set.
- non-revertive
The current standby MAG-u can only be selected as the active MAG-u if the PFCP association of the current active MAG-u is removed or if the MAG-u is considered failed (see MAG-u health determination), or if the MAG-u is in lockout state (see MAG-u lockout). Otherwise, the current active MAG-u is always reselected as the active MAG-u.
configure mobile-gateway profile bng fsg-profile active-standby-selection active-change-without-failureThe following command options are available:
- always
The MAG-c always uses the revertive mode.
- never
The MAG-c always uses the non-revertive mode.
- initial-only
The MAG-c uses the revertive behavior for a short period after the first MAG-u PFCP association for the FSG was set up. After that short period, the MAG-c automatically switches to the non-revertive mode. This option is useful when the non-revertive mode is required but a predictable active/standby MAG-u is expected during startup of the MAG-u and MAG-c; for example, to select the preferred MAG-u at startup. When the never option is set, the first MAG-u to come up is always selected as active (and that does not change), independent of its preferred state.
- time-of-day
The MAG-c uses the revertive behavior each day during a specified time period. This option is useful to allow revertive mode at times when impact is expected to be low. In addition, the MAG-c automatically triggers a reselection procedure of all FSGs at the start of this period to allow changes under relaxed revertiveness conditions.
tools perform mobile-gateway pdn bng up-resiliency force-reselection up-groupIf the standby MAG-u becomes active, the active MAG-u automatically becomes standby. The MAG-c takes no further action.
The MAG-c selects a standby MAG-u independent of the revertive mode configuration.
Both the revertive active MAG-u and the standby MAG-u are selected using the following criteria. This is a fall-through list that stops as soon as there is only one MAG-u that meets all the criteria. Any MAG-u for which the PFCP association is down or which is in lockout is not considered.
- the MAG-u with the highest health (see MAG-u health determination)
- the preferred MAG-u
- the MAG-u
with the lowest number of sessions, simulated as if the FSG would move to that MAG-uNote: To avoid unnecessary FSG changes when the number of sessions on several MAG-u nodes is very similar, the MAG-c applies a weight multiplier to the FSG session count when it simulates a move to a different MAG-u than the current one.
- the MAG-u with the lowest amount of FSGs, excluding the current FSG, with the goal to provide initial load balancing when no sessions are set up
- the current state of the MAG-u, where the current active MAG-u has priority over the current standby MAG-u that has priority over any backup MAG-u to avoid any unnecessary active or standby changes if all else is equal
- the MAG-u with the lowest IP used in PFCP signaling, with no specific goal other than to have a deterministic tiebreaker when all else is equal
If the result of the active/standby selection differs from the current active/standby selection, the MAG-c initiates an active/standby change.
If the result of the active/standby selection is the same as the current active/standby selection, but the health of any MAG-u has changed from unavailable (-1) to 0% or higher, the MAG-c also initiates an active/standby change.
Otherwise, the MAG-c takes no further action.
Active/standby change or switchover
If the active/standby selection results in a new active or new standby MAG-u, the MAG-c executes the change on the MAG-u nodes as follows:
- The MAG-c updates the PFCP FSG state on all involved MAG-u
nodes.
The change procedure ends if the active MAG-u does not positively confirm. If the active MAG-u change times out or explicitly returns an error, the MAG-c rolls back the changed FSG states and stops the active/standby change procedure.
Changes to other MAG-u nodes (for example, standby MAG-u nodes) may fail. This is even expected in some cases; for example, in 1:1 deployments where the previously active MAG-u has failed and becomes standby, the failed MAG-u is not expected to respond.
A MAG-u that explicitly rejects an explicit FSG update is put into lockout. This triggers a degradation reselection, which is handled as soon as the change is completed. See MAG-u lockout for more information.
- When the active MAG-u
confirms the FSG change, the MAG-c starts updating the PFCP session states. The exact update for each session
depends on the change and the session resiliency model, as follows:
- Hot standby, active/standby switch
No updates to the MAG-u nodes are needed.
- Hot standby, new standby MAG-u
The MAG-c establishes the session on the new standby MAG-u and deletes it from the previous standby MAG-u if there was one.
- Hot standby, health change only
This acts as a trigger to reinstall missing standby sessions on the standby MAG-u.
- Hot standby, active/standby switch
- When the standby MAG-u confirms the FSG change, the MAG-c sends a second FSG update message to the active MAG-u without changing anything. This can be done in parallel with the previous step. The second FSG update message may seem redundant, but is required to resolve a rare race condition in the GARP/ARP signaling for fixed access connections.
- When the change is completed, the MAG-c evaluates whether the current active/standby state matches the expected active/standby state by running the selection logic again (see Active/standby selection). If the states do not match, the MAG-c automatically triggers a recovery reselection and starts the recovery hold timer (see Active/standby selection triggers).
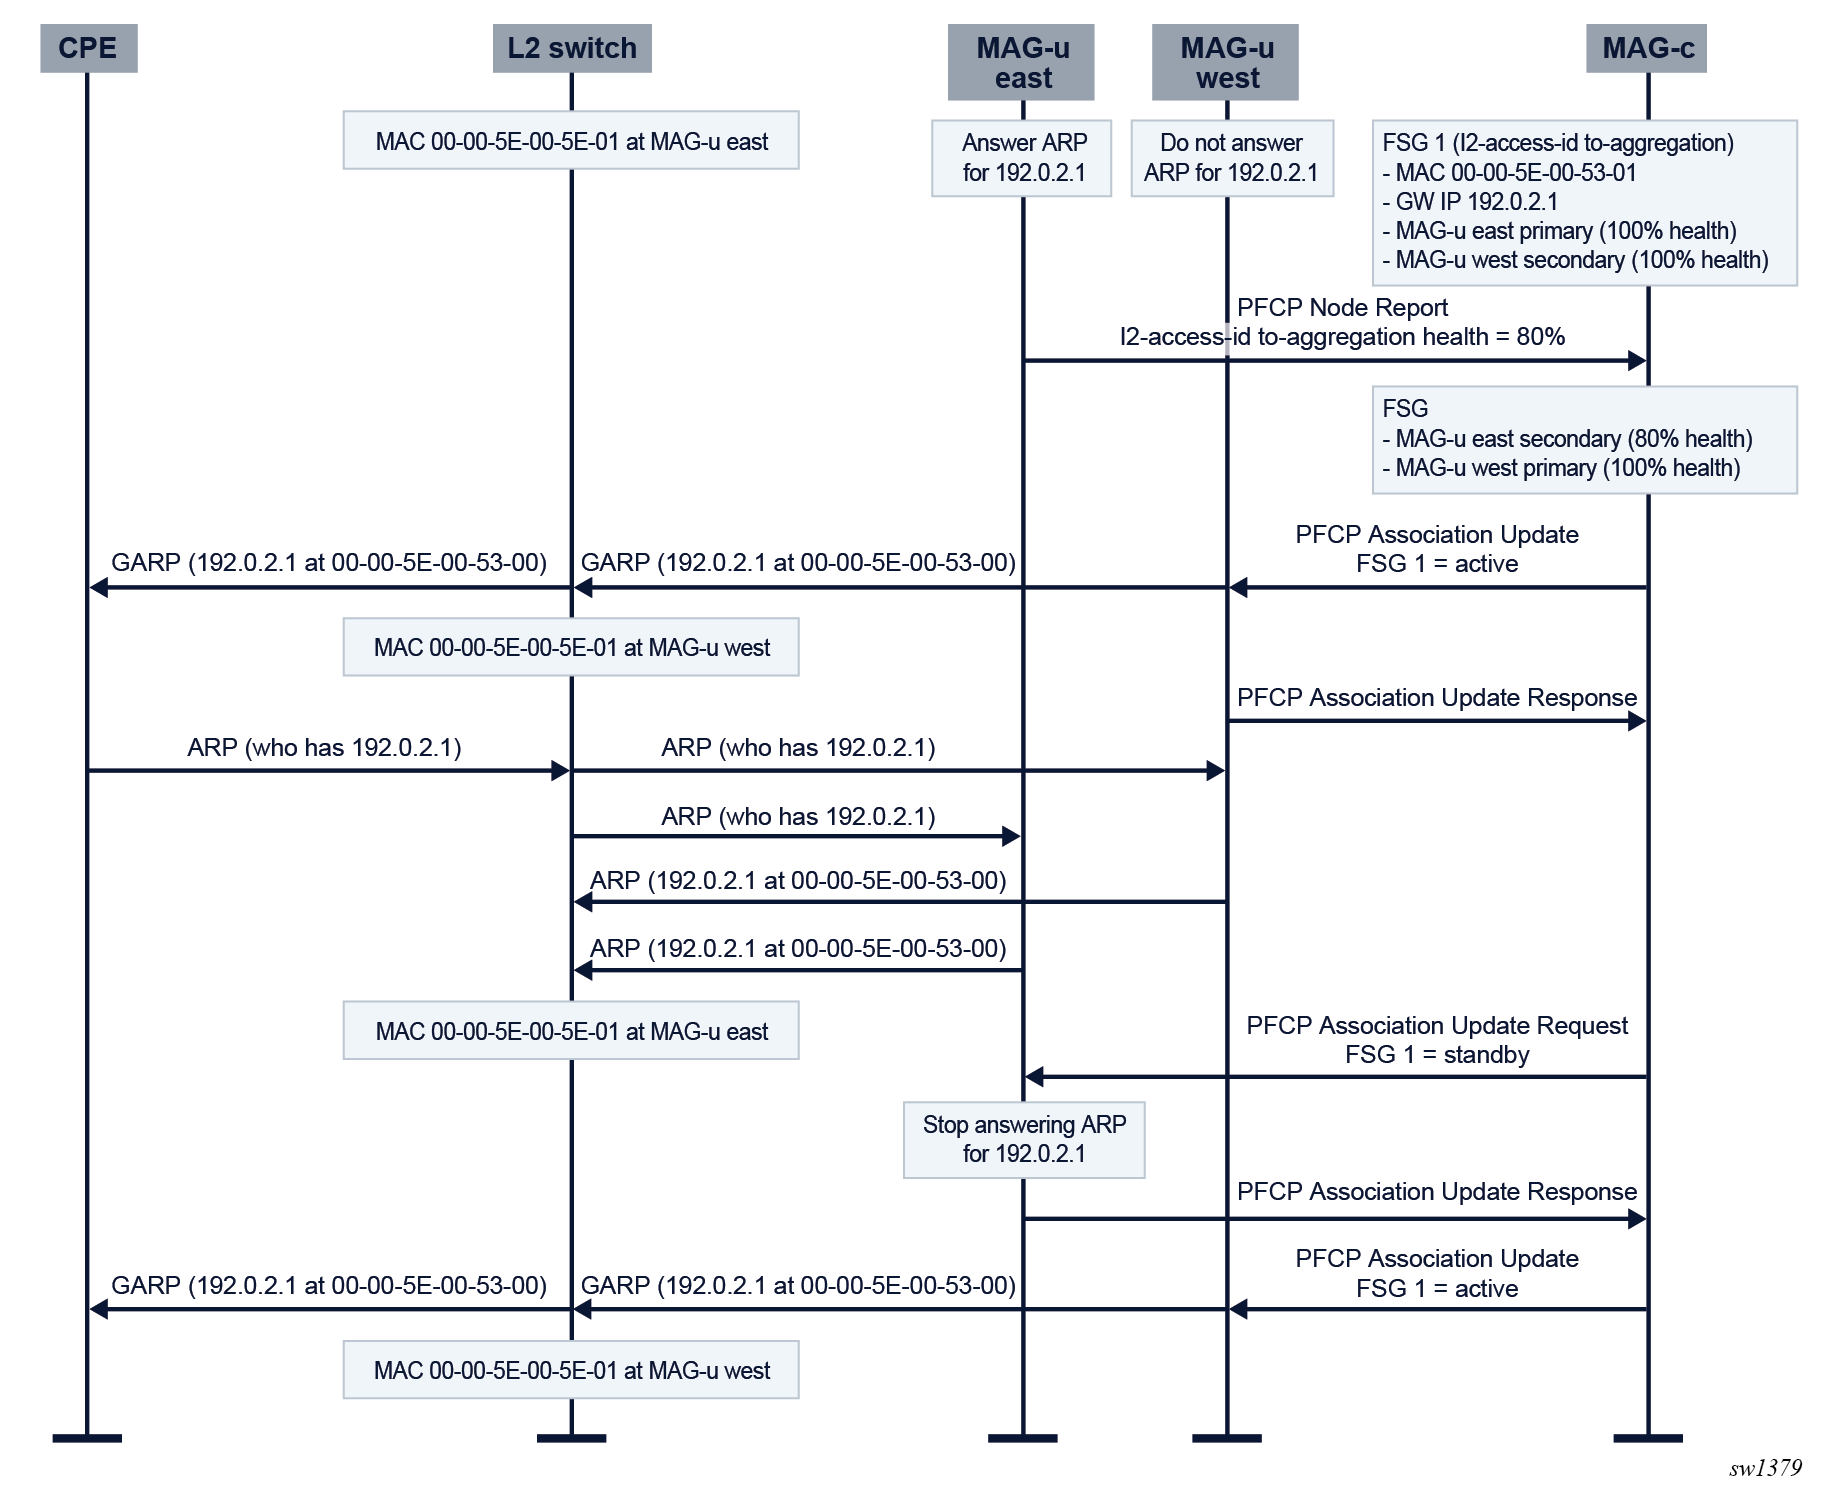
GARP/ARP race conditions
Fixed access connections use per-FSG MAC addresses to attract traffic (see Traffic steering parameters). Most Layer 2 aggregation switches keep a forwarding database (FDB) that points each gateway MAC address to the correct MAG-u to avoid broadcasting traffic. The FDBs are populated by snooping ARP and ND messages. To expedite updates of the FDBs during active/standby switchovers, the Nokia MAG-u generates a gratuitous ARP (GARP) message with the FSG MAC address when the FSG is signaled to become active. However, in a very exceptional case, a single GARP is not enough when the following conditions apply:
- The new standby MAG-u has not yet processed the message that asks it to become standby.
- A regular ARP is sent and broadcast as normal.
- Both MAG-u nodes answer, and the ARP response from the new standby MAG-u comes later than the ARP response of the new active MAG-u.
If the preceding conditions apply, the Layer 2 aggregation switch has a wrong FDB entry. Sending a second update to the new active MAG-u can act as a new GARP trigger to correct the situation. The following figure shows this case.
MAG-u lockout
- an explicit FSG error from the MAG-u when signaling an FSG create, modify, or delete
- the path of a MAG-u
goes down, in addition to setting its health to -1 (unavailable) (see MAG-u health determination)Note: This only applies to a full PFCP path down, and not to headless mode. For more information about the differences, see Headless mode. For more information about the interaction of MAG-u resiliency with headless mode, see Interaction with headless mode.
The MAG-c sees placing a MAG-u in lockout as a degradation trigger for the FSG (see Active/standby selection triggers). The MAG-c attempts to remove the locked out MAG-u from being selected as either active or standby (see Active/standby selection).
configure mobile-gateway profile bng fsg-profile active-standby-selection failure-lockout- If the MAG-u is not active or standby for the FSG, the MAG-c removes the lockout state and triggers a recovery reselection for the FSG.
- Otherwise, the MAG-c restarts the lockout timer with a fixed value and takes no further action. This guarantees that the MAG-u is removed from the FSG at least one time and starts from a clean slate before it can be made active or standby again.
Monitoring ongoing FSG changes
show mobile-gateway pdn bng fsgstate mobile-gateway pdn bng fsg- Current Hold-Off Delay
This field indicates if a received change trigger is subject to a hold-off period. If the displayed value is 0 msec, no change triggers are held off. See Active/standby selection triggers for more information about change triggers and the hold time.
- Active Changing
This field indicates if a change of the active MAG-u is ongoing. If the displayed value is no, the active MAG-u is not being changed; if it is yes, the active MAG-u is being changed.
- Locked
This field indicates if a MAG-u is currently in the lockout state. If the displayed value is no, the MAG-u is not in the lockout state. Any other value indicates that the MAG-u is in the lockout state for the duration indicated by the value. This is an important indicator because a locked out MAG-u periodically attempts to get out of lockout, which triggers an FSG change. See MAG-u lockout for more information about lockout.
- Standby ReadyThis field indicates if a change of the standby MAG-u is ongoing. If the displayed value is yes, the standby MAG-u is not being changed; if it is no, the standby MAG-u is being changed or is in another condition where it is unfit to replace the active MAG-u, for example, because it is in drain state. In case of the hot standby resiliency model, a change of the standby MAG-u can take time if sessions have to be recreated on the standby MAG-u. Use the following command to estimate how many sessions still have to be created.
show mobile-gateway bng session standby-state hot-to-create count
FSG with two MAG-u nodes
A:MAG-c# show mobile-gateway pdn bng fsg 1
===============================================================================
Fate Sharing Group 1
===============================================================================
PDN gateway                          : 1
Up-Group                             : broadcast_domain
No. Of Sessions                      : 0
Current Hold-Off Delay               : 0 msec
Virtual MAC                          : 02:00:5e:00:00:01

FSG Profile                          : basic
    Default Standby Type             : hot

Active UP                            : up-east (192.0.2.11)
    Active Changing                  : no
    Locked                           : no
    Preferred                        : yes
    Drain                            : no
    Health                           : 100
    S-Vlan Range                     : N/A
    C-Vlan Range                     : N/A

Standby UP                           : up-west (192.0.2.12)
    Standby Ready                    : yes
    Locked                           : no
    Preferred                        : no
    Drain                            : no
    Health                           : 100
    S-Vlan Range                     : N/A
    C-Vlan Range                     : N/A
===============================================================================
Hot standby
In the context of MAG-u resiliency, hot standby is a per-session concept that defines how a session is handled on the standby MAG-u. Hot standby sessions are precreated on the standby MAG-u, which can start forwarding traffic for those sessions as soon as it becomes active. This offers significantly reduced forwarding loss during switchovers, and depending on the capabilities of the aggregation network, it may even be possible to achieve non-loss planned switchovers; for example, to seamlessly handle MAG-u upgrades.
For hot standby, any procedure that interacts with a MAG-u (for example, a CoA with a QoS update) first applies the change on the active MAG-u. If the change succeeds, the procedure continues as usual and updates the standby MAG-u in parallel. In the unlikely event that only the standby MAG-u update fails, the MAG-c does not fail the triggering procedure. Instead, it tries to reapply the update periodically in the background until the standby MAG-u is realigned with the active MAG-u. If this realignment is not resolved when the standby MAG-u becomes active, the MAG-c removes the full session.
Interaction with headless mode
MAG-u resiliency is supported in combination with the MAG-u headless mode (see Headless mode). When a MAG-u becomes headless, its health becomes unavailable (-1) because the MAG-c cannot differentiate between a MAG-u toward which communication failed (headless) or a MAG-u that completely failed. See MAG-u health determination for more information.
A MAG-u becoming headless acts as a trigger to perform a potential switchover from active to standby. A switchover cannot be signaled to the headless MAG-u, which operates on stale data. The Nokia MAG-u, by default, uses a heuristic process to determine whether to keep FSGs active or make them standby during headless operations. In rare cases, the MAG-u may keep an FSG active while the MAG-c has successfully made another MAG-u active. As a result, there is an active/active forwarding situation in which both the headless and non-headless MAG-u nodes of an FSG have an active state. In this scenario, the following applies:
- Uplink QoS cannot always be guaranteed because traffic may switch from one MAG-u to
the other at any time. After headless recovery, the active/standby situation
stabilizes and traffic flows through only one MAG-u with
normal QoS guarantees.Note: Downlink QoS can still be guaranteed when the non-headless MAG-u announces routes with a higher preference than the headless MAG-u to consistently forward downlink traffic through the non-headless MAG-u. Additionally, if the access network updates its uplink forwarding based on downlink traffic, uplink traffic is forwarded through the non-headless MAG-u.
- Accounting reports may be off because traffic on the headless MAG-u is not counted. After headless recovery, the MAG-c can fetch the missing statistics and the accounting is corrected.
- If there is unicast replication in the access network, these packets may end up being replicated also in the data network. However, this is extremely unlikely as the FSG MAC is most likely known at any point in time.
For more information about the headless heuristics and the downlink routing differentiation, see the 7750 SR and VSR BNG CUPS User Plane Function Guide.
- When a single MAG-u is headless, that MAG-u makes its FSGs standby and the MAG-c makes the other MAG-u active. This results in an active/standby state as expected.
- When both MAG-u nodes are headless, for example, because of a networking issue at the MAG-c, the FSG becomes standby on all MAG-u nodes and all traffic is dropped.
Operational commands
The same operational commands can be used for resilient sessions as for nonresilient sessions. See Operational commands and debugging.
show mobile-gateway pdn bng- up-group
This command provides an overview of all configured UP groups, and the number of sessions and MAG-u nodes that are currently active in the UP groups.
- up-group
group-name
This command provides an overview of the specific UP group, the associated list of FSGs, and the associated MAG-u nodes.
- fsgThis command provides an overview of the UP group of the specific FSG and the current active/standby MAG-u nodes. This is useful to quickly retrieve information when a specific FSG ID is known. The following are examples to get a specific FSG ID:
- from a command in the following
context
show mobile-gateway bng session - from a MAG-u-specific operational command
- from a command in the following
context
- up
This command provides an overview of all MAG-u nodes and their UP group participation. The applicable Layer 2 access ID, the applicable VLAN range, and the active/standby state for the MAG-u in the UP group are displayed.